List craers—more commonly referred to in technical and professional contexts as "list crawlers"—are specialized software agents or automated scripts designed to systematically navigate, index, and extract structured data from digital lists, directories, and web-based repositories. These tools serve as the backbone for data aggregation, allowing users to transform decentralized, raw web information into organized datasets that support research, market analysis, and logistical planning. By mimicking the behavior of a standard web browser, a list crawler systematically visits defined URLs, parses the HTML or JSON structure of the pages, and exports the gathered information into formats like CSV, Excel, or SQL databases for further manipulation.
The Mechanism of List Crawlers
At its core, a list crawler operates through a series of automated "visits" to specified web pages. When a user provides a starting point—often a directory page containing a list of links—the crawler initiates a request-response cycle. It requests the page's source code, interprets the markup (typically HTML), and follows a set of pre-defined rules, often referred to as "selectors," to identify specific data points.
These data points usually consist of items such as names, contact details, product specifications, or service descriptions. Once the crawler identifies an item, it stores the associated attributes in a local data structure. Many advanced crawlers are programmed to follow sub-links (pagination or individual detail pages) to ensure comprehensive coverage of a specific list, moving from a primary directory page to hundreds or thousands of secondary pages.
Prerequisites for Effective Crawling
Before deploying a crawler, you must ensure that your technical environment and ethical framework are prepared for the task. Effective data collection is not merely about having the right software; it is about respecting the target environment and ensuring the data is gathered in a way that remains usable and legal.
- Network Stability and Environment: Crawlers require a reliable, high-bandwidth internet connection to handle the volume of requests. It is often necessary to use a machine with a static IP or a rotating proxy service to avoid being blocked by rate-limiting security protocols.
- Infrastructure Requirements: Depending on the scale, you may run these scripts on a local workstation or a cloud-based server. Using cloud infrastructure, such as virtual private servers (VPS), is generally recommended for large-scale extraction to ensure the process does not interfere with your local machine's performance.
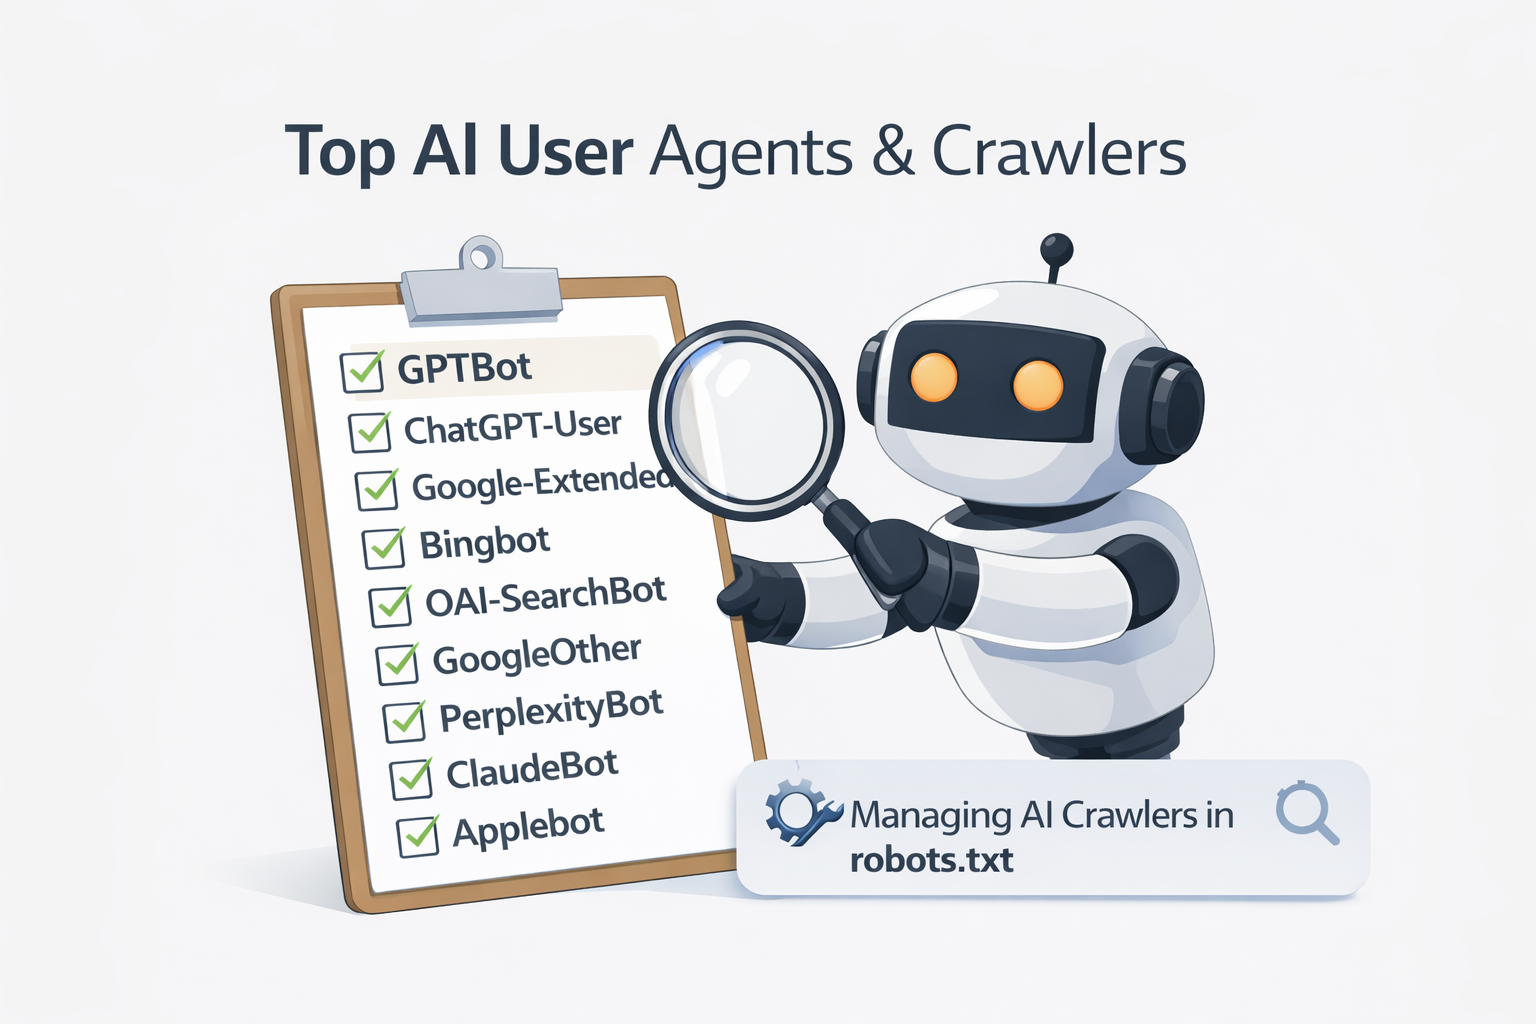
- Target Analysis: Before initiating a crawl, manually inspect the target website. Look for "Terms of Service" (ToS) documents, which often detail restrictions on automated access. Additionally, check the
robots.txtfile (located atexample.com/robots.txt) to determine which areas of the site the owner permits or restricts from automated indexing.
Navigating Technical and Ethical Boundaries
When using list crawlers, one of the most critical considerations is the "politeness" of the script. This refers to the intentional delays placed between requests. A crawler that makes requests too rapidly can be interpreted as a Denial-of-Service (DoS) attack, causing the host server to crash or resulting in your IP address being permanently blacklisted.
Professional-grade crawlers incorporate randomized delays, often referred to as "sleep" commands, which mimic human browsing behavior. This ensures that the server is not overwhelmed and that your activity appears as legitimate traffic. Furthermore, maintaining compliance with privacy laws—such as the GDPR in the European Union or the CCPA in California—is mandatory if the lists you are crawling contain personal identifying information (PII). Ensure that any data you collect complies with your local jurisdiction’s regulations regarding the processing and storage of sensitive information.
Comparing Methods: Manual vs. Automated Extraction
The decision to use an automated list crawler versus manual data entry depends heavily on the volume of the data and the frequency of the required updates.
| Feature | Manual Extraction | Automated List Crawler |
|---|---|---|
| Data Volume | Low (hundreds of items) | High (thousands to millions) |
| Accuracy | High (Human oversight) | Variable (Dependent on scripts) |
| Speed | Extremely Slow | Very Fast |
| Cost | Low (Labor hours) | Moderate (Tooling/Proxy costs) |
| Maintenance | None required | High (Fixing broken selectors) |
Manual extraction is generally suitable for small, one-time tasks where the risk of error must be near zero. However, when the list changes frequently or contains thousands of entries, the human cost becomes unsustainable, making a list crawler the more logical and efficient investment.
Common Troubleshooting and Maintenance
Even the most robust list crawler will eventually face "failure points." These occur when the structure of the target website changes. Because crawlers rely on fixed patterns (such as identifying that a price is always inside a tag with the class price), any update to the website's design can cause the crawler to collect empty data or crash.
- Selector Failures: If your crawler stops returning data, the first step is to verify if the CSS selectors or XPaths used to identify elements are still valid. Open the developer tools in your browser (F12) to inspect the target page and update your script’s identifiers accordingly.
- IP Blocks: If you encounter 403 Forbidden or 429 Too Many Requests errors, your IP is likely being throttled. Implement proxy rotation or increase the delay between page requests to restore access.
- Data Integrity: Regularly audit your exported files. Look for null values or inconsistent formatting. Standardizing the data, such as removing currency symbols from price strings or normalizing phone number formats, should be an integral part of your post-processing pipeline.
Integration with Analytical Workflows
Once your list crawler has successfully extracted the raw data, the final and most important phase is analysis. A list is only as valuable as the insights derived from it. For example, if you are crawling a product directory, you might use the data to create a price-tracking dashboard. If you are crawling professional directories, you might use the data to map regional service distribution or identify competitive gaps in a market.
Exporting to SQL databases is recommended for long-term projects. Unlike CSV files, which are static, a database allows you to query historical trends. You can compare the current list against last month's data to track changes in availability, pricing, or business information.
Frequently Asked Questions
Are list crawlers legal to use? In general, collecting publicly available information from the web is legal in many jurisdictions, provided it does not violate copyright laws or the target site's Terms of Service. However, you must avoid bypassing security measures or scraping private, password-protected areas. Consult a legal expert if you intend to commercialize the data you collect.
What is the best language to build a list crawler? Python is the industry standard for crawling due to its robust ecosystem of libraries such as Scrapy, BeautifulSoup, and Selenium. These libraries provide pre-built functions for handling HTTP requests, parsing HTML, and managing asynchronous tasks.
How do I handle pages that require JavaScript to load? Standard HTML parsers often fail on modern, dynamic websites that use JavaScript frameworks like React or Vue. For these, you must use a "headless browser" tool like Playwright or Selenium, which renders the entire page content as a real browser would before the crawler attempts to extract data.
What is a proxy, and why is it needed? A proxy acts as an intermediary between your computer and the target website. By routing your requests through various proxy servers, you can mask your true IP address and avoid site-specific bans. This is essential for large-scale crawling where single-IP traffic would be quickly blocked.
How often should I run my crawler? The frequency depends on your specific needs. If you are tracking real-time price fluctuations, you may need to run the crawler every hour. If you are building a database of company contacts, a weekly or monthly update is usually sufficient to maintain data accuracy without taxing the target server.
Next Actions
To successfully implement a crawler, begin by choosing a target directory that is well-structured and does not have restrictive anti-crawling measures. If you are new to this field, start with the Python BeautifulSoup library, as it is well-documented and ideal for learning the basics of HTML parsing. Draft your script to target a single page first to ensure your selectors are correct. Once you can reliably extract data from one page, scale your script to iterate through a list of URLs. Always start small, maintain a polite request rate, and prioritize the cleanliness of your resulting database.