Core search represents the fundamental retrieval engine mechanics that match user intent with indexed digital information, relying on complex ranking algorithms, natural language processing, and semantic analysis to deliver precise results. Understanding how these baseline systems evaluate relevance, authority, and user experience is essential for developers, information architects, and content strategists seeking to optimize discoverability across modern digital platforms.
The Foundations of Core Search Architecture
At its heart, core search is the foundational machinery powering information retrieval systems. Whether deployed across enterprise databases, e-commerce catalogues, or global web-scale indexes, the primary objective remains identical: to ingest, process, store, and rank vast amounts of unstructured or semi-structured data to answer user queries with maximum precision and minimal latency.
Modern core search architectures do not merely look for exact string matches. Instead, they rely on a sophisticated multi-stage pipeline designed to understand human intent, parse complex semantic relationships, and evaluate the quality of the underlying sources. This evolution shifts search from a mechanical keyword lookup tool into an intelligent computational partner capable of contextual reasoning.
Ingestion, Crawling, and Document Parsing
The search lifecycle begins long before a user types a query into a search box. It starts with data acquisition. In web-scale environments, specialized automated bots—often referred to as crawlers or spiders—traverse the public internet, discovering new URLs, following links, and downloading raw HTML, document files, and media assets. In enterprise contexts, ingestion mechanisms connect directly to content management systems, relational databases, cloud storage buckets, and application programming interfaces (APIs) to pull internal documents.
Once raw data is acquired, parsing engines break down the content. They strip away irrelevant code, isolate metadata, extract headings, and segment text into manageable chunks. This parsed content is then normalized—a process that converts all characters to a uniform case, removes punctuation, and standardizes encodings. Without this rigorous preparation, downstream ranking algorithms would fail to process data uniformly.
Tokenization, Lemmatization, and Stemming
After normalization, the text undergoes linguistic processing. Tokenization is the process of breaking a continuous stream of text into individual units, known as tokens (typically words or sub-words).
Following tokenization, search engines apply morphological reduction techniques to collapse various grammatical forms of a word into a single base representation:
- Stemming: A heuristic process that chops off the ends of words to arrive at a root form, which may not be a valid linguistic word (e.g., reducing "running," "runner," and "runs" to "run").
- Lemmatization: A more sophisticated, vocabulary-based approach that uses dictionaries and morphological analysis to return the proper base form or dictionary form of a word, known as the lemma (e.g., reducing "better" to "good").
These linguistic steps ensure that a search for "running shoes" successfully matches a document discussing "a runner who ran yesterday."
Indexing Mechanics and the Inverted Index
Once documents are tokenized and processed, they cannot be stored in a way that requires the system to scan every single document from scratch every time a query is executed. That approach would cause catastrophic performance bottlenecks. Instead, search engines build specialized data structures known as inverted indexes.
An inverted index flips the relationship between documents and words. Rather than listing every word found inside Document A, Document B, and Document C, an inverted index lists every unique word (or term) and maps it directly to the exact documents where that term appears, along with positional metadata (such as word frequency and character offsets).
The Anatomy of an Inverted Index
To understand how an inverted index functions under the hood, consider a simplified three-document database:
- Document 1: "Core search algorithms rank documents."
- Document 2: "Search algorithms analyze relevance."
- Document 3: "Core relevance involves ranking."
An inverted index maps these terms as follows:
| Term | Document Postings (Term Frequency, Positions) |
|---|---|
| Algorithms | Doc 1 (Pos: 3), Doc 2 (Pos: 2) |
| Core | Doc 1 (Pos: 1), Doc 3 (Pos: 1) |
| Documents | Doc 1 (Pos: 4) |
| Rank | Doc 1 (Pos: 2) |
| Ranking | Doc 3 (Pos: 4) |
| Relevance | Doc 2 (Pos: 3), Doc 3 (Pos: 2) |
| Search | Doc 1 (Pos: 2), Doc 2 (Pos: 1) |
When a user submits the query "core search," the search engine consults the inverted index, isolates the postings for "core" (Docs 1 and 3) and "search" (Docs 1 and 2), calculates the intersection (Doc 1), and passes that subset forward to the scoring phase. This structural efficiency allows modern systems to query billions of documents in milliseconds.
Query Understanding and Intent Matching
Raw indexing provides candidate documents, but returning the right documents requires deep query understanding. When a user submits a search string, the core search engine must decipher what the user actually wants. This phase involves syntactic analysis, spelling correction, synonym expansion, and intent classification.
Types of Search Intent
Search intent is generally categorized into distinct buckets that dictate how the search engine structures its results page:
- Informational Intent: The user wants to learn about a specific topic, concept, or question (e.g., "how do inverted indexes work").
- Navigational Intent: The user is looking for a specific website, brand, or portal (e.g., "GitHub login").
- Transactional Intent: The user intends to complete an action, purchase a product, or download software (e.g., "buy enterprise search software").
- Commercial Investigation: The user is comparing options prior to making a purchasing decision (e.g., "Elasticsearch vs Apache Solr").
Core search algorithms analyze query phrasing, historical click-through patterns, and entity relationships to determine the dominant intent. If a query has ambiguous intent, modern search engines often diversify the result set to cover multiple potential interpretations.
Relevance Scoring Models and Ranking Signals
Once candidate documents are retrieved and intent is established, the core search engine scores and ranks the documents. Scoring is a mathematical evaluation of how well a given document satisfies the query. Over decades of information retrieval research, scoring models have evolved from simple term-matching heuristics to complex machine learning pipelines.
Term Frequency-Inverse Document Frequency (TF-IDF)
Historically, TF-IDF served as the statistical bedrock for document scoring. It balances two competing factors:
- Term Frequency (TF): How often a term appears within a specific document. Higher frequency suggests higher relevance, up to a point.
- Inverse Document Frequency (IDF): A measure of how rare a term is across the entire corpus. Common words like "the" or "and" have a low IDF, while niche terms like "lemmatization" have a high IDF.
By multiplying TF by IDF, search engines assign higher scores to documents that mention a query term frequently, provided that the term is relatively rare across the rest of the database.
BM25 (Best Matching 25)
While TF-IDF is powerful, it suffers from linear scaling—meaning ten instances of a keyword are treated as twice as relevant as five instances, even if the fifth instance provides no additional value. BM25 is an advanced probabilistic ranking function that introduces term frequency saturation. Once a term appears a certain number of times in a document, additional mentions yield diminishing returns. BM25 remains a standard baseline scoring function in modern search platforms like Apache Lucene, Elasticsearch, and OpenSearch.
Vector Search and Semantic Embeddings
With the advent of transformer-based machine learning models, core search has expanded beyond lexical matching into vector search. Vector search translates words, sentences, or entire documents into dense numerical vectors (embeddings) within a high-dimensional semantic space.
Instead of matching exact keywords, vector search calculates the geometric distance (such as cosine similarity) between a user's query vector and the document vectors. This enables semantic search, allowing systems to retrieve relevant results even when the document shares zero common keywords with the query, successfully bridging the vocabulary gap between human phrasing and written documentation.
Optimization Strategies for Core Search Performance
Optimizing content and applications for core search engines requires a dual approach: technical optimization to ensure efficient crawling, parsing, and indexing; and semantic optimization to align content with user intent and ranking algorithms.
1. Technical Prerequisites and Crawl Budget Management
- Clean Information Architecture: Ensure logical URL structures, clean site hierarchies, and robust internal linking to help crawlers discover deep pages.
- Structured Data Implementation: Utilize Schema.org markup to explicitly define entities, products, articles, and organizational data, helping parsers understand content context.
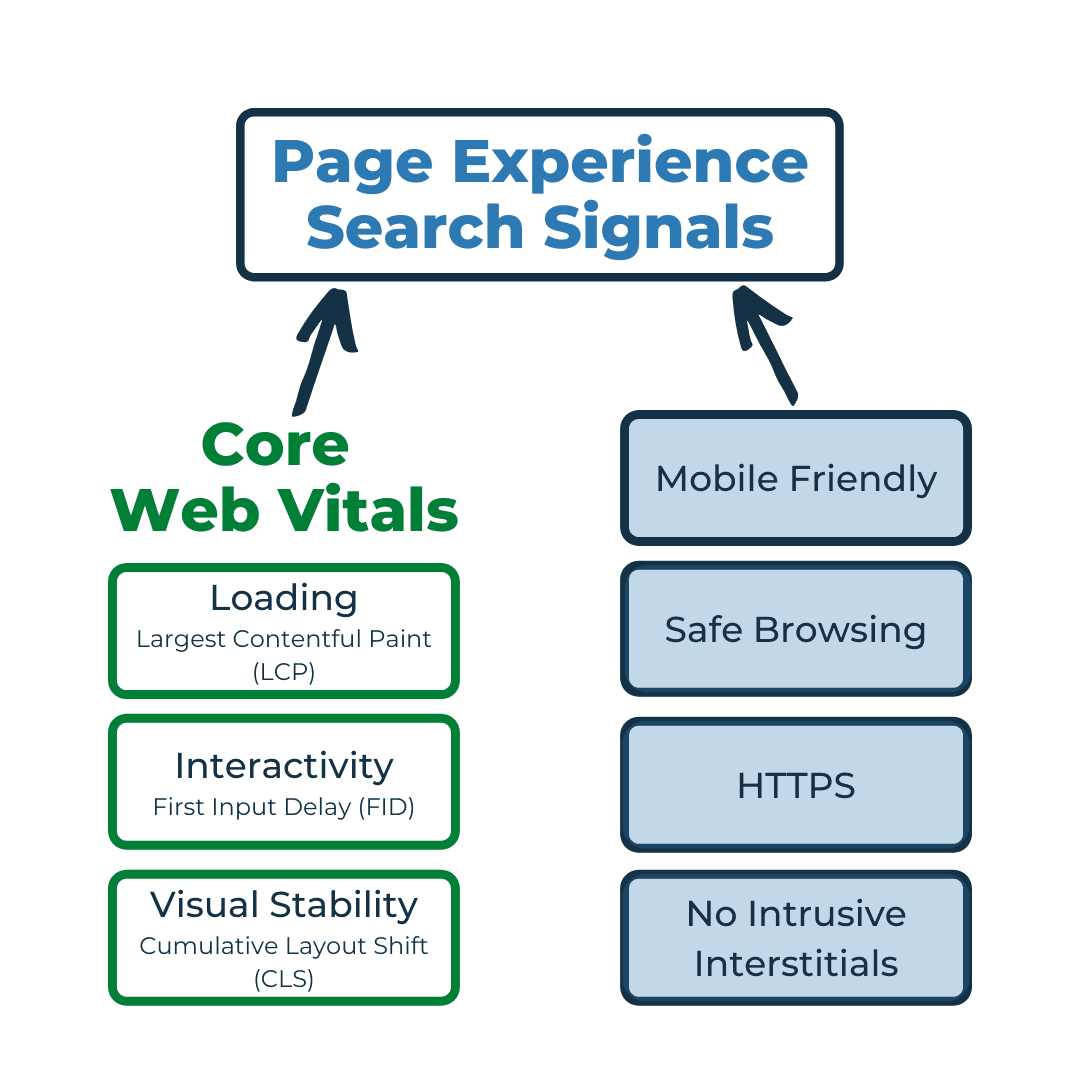
- Performance Optimization: Minimize page load latency, optimize server response times, and ensure mobile responsiveness, as performance metrics frequently tie directly into ranking algorithms.
2. Semantic Content Alignment
- Comprehensive Topic Coverage: Address user queries thoroughly by exploring related subtopics, answering adjacent questions, and providing deep context rather than superficial overviews.
- Entity-Driven Writing: Focus on clear noun phrases, recognized industry terminology, and unambiguous entity references that machine learning models can easily parse and cluster.
- Natural Language Optimization: Write for human comprehension while maintaining clear structural hierarchies using proper H1, H2, and H3 HTML heading tags.
Common Mistakes in Search Configuration and Content Strategy
Implementing or optimizing a core search system is fraught with potential pitfalls. Avoiding these common mistakes prevents indexing failures and poor user experiences:
- Over-Optimizing for Keyword Density: Stuffing unnatural keyword variations into text degrades readability and triggers spam filters in modern machine learning-based rankers.
- Neglecting Search Analytics: Failing to monitor zero-result queries, click-through rates, and user drop-off points leaves administrators blind to shifting user intent.
- Ignoring Dynamic Content Rendering: Relying heavily on client-side JavaScript without server-side rendering or pre-rendering can prevent search bots from indexing crucial page content.
- Failing to Maintain Synonyms and Stopwords: Omitting domain-specific stopword lists or custom synonym dictionaries can blind a search engine to industry jargon used by its target audience.
Frequently Asked Questions About Core Search
What is the difference between lexical search and semantic search?
Lexical search relies on exact keyword matching, stemming, and statistical term frequency formulas like BM25 to find documents containing the user's exact words. Semantic search uses vector embeddings and machine learning models to understand the underlying intent and meaning of a query, allowing it to retrieve relevant documents even if they use completely different terminology.
How does an inverted index improve search speed?
An inverted index pre-processes documents by mapping unique terms directly to their corresponding document locations. When a query is executed, the search engine only evaluates the specific postings list for those terms, bypassing the need to scan every document in the database sequentially.
Why is document parsing important for core search engines?
Document parsing cleans raw incoming data by stripping away unnecessary code, extracting structural metadata, and normalizing text encodings. Without proper parsing, search engines would process noisy formatting characters as meaningful terms, severely degrading search accuracy.
What role do vector embeddings play in modern search?
Vector embeddings convert text into multi-dimensional numerical arrays that capture semantic relationships. Modern search engines use these vectors to calculate conceptual similarity between queries and documents, enabling advanced natural language understanding and cross-lingual search capabilities.
How can I improve the search discoverability of technical documentation?
Improve discoverability by implementing clean hierarchical heading structures, utilizing descriptive semantic markup (such as Schema.org), maintaining consistent domain-specific terminology, and ensuring fast server response times for efficient crawler indexing.
Conclusion and Next Actions
Mastering core search requires understanding the entire retrieval lifecycle—from raw data ingestion and inverted indexing to advanced semantic scoring models and intent matching. Whether you are tuning an enterprise search engine or optimizing web content for public discovery, success depends on balancing robust technical architecture with clear, intent-aligned content.
To take immediate action, audit your current search analytics to identify zero-result queries, review your information architecture for crawl bottlenecks, and ensure your content utilizes clear structural markup and comprehensive semantic depth.