Monitoring Microsoft Azure status is essential for maintaining cloud infrastructure reliability, diagnosing unexpected downtime, and ensuring business continuity for applications hosted in enterprise environments. By leveraging official status dashboards, service health notifications, and programmatic health APIs, IT professionals, developers, and cloud administrators can track real-time outages, planned maintenance events, and regional health metrics across the global Azure ecosystem.
Understanding Azure Status and Cloud Reliability
Cloud computing relies on distributed infrastructure spanning dozens of geographic regions and availability zones. When deploying mission-critical workloads on Microsoft Azure, maintaining high availability requires continuous visibility into the operational state of underlying cloud services. Azure status refers to the collective health, availability, and performance metrics of Microsoft’s cloud computing services, ranging from core compute engines like Virtual Machines and Azure Kubernetes Service (AKS) to specialized data stores like Azure SQL Database and Cosmos DB.
Unlike traditional on-premises infrastructure where hardware failures are handled internally by local IT teams, cloud infrastructure management depends on a shared responsibility model. While customers are responsible for application architecture, data replication, and failover configurations, Microsoft is responsible for the physical data centers, host hardware, network fabrics, and foundational service orchestration. When disruptions occur on the provider side, understanding the scope, root cause, and estimated remediation time of the incident is vital for effective incident management and stakeholder communication.
System administrators and DevOps engineers utilize Azure status tools not only reactively during outages but also proactively to anticipate regional network degradations, security advisories, and scheduled hardware maintenance windows. Integrating health monitoring into daily operations reduces mean time to detection (MTTD) and mean time to resolution (MTTR), safeguarding enterprise service-level agreements (SLAs).
Official Channels for Checking Azure Status
Microsoft provides multiple dedicated channels for monitoring platform health, tailored to different personas ranging from executive stakeholders to automated monitoring systems. Knowing which tool to consult depends on whether you require a high-level public overview or granular, resource-specific diagnostic telemetry.
The Public Azure Status Dashboard
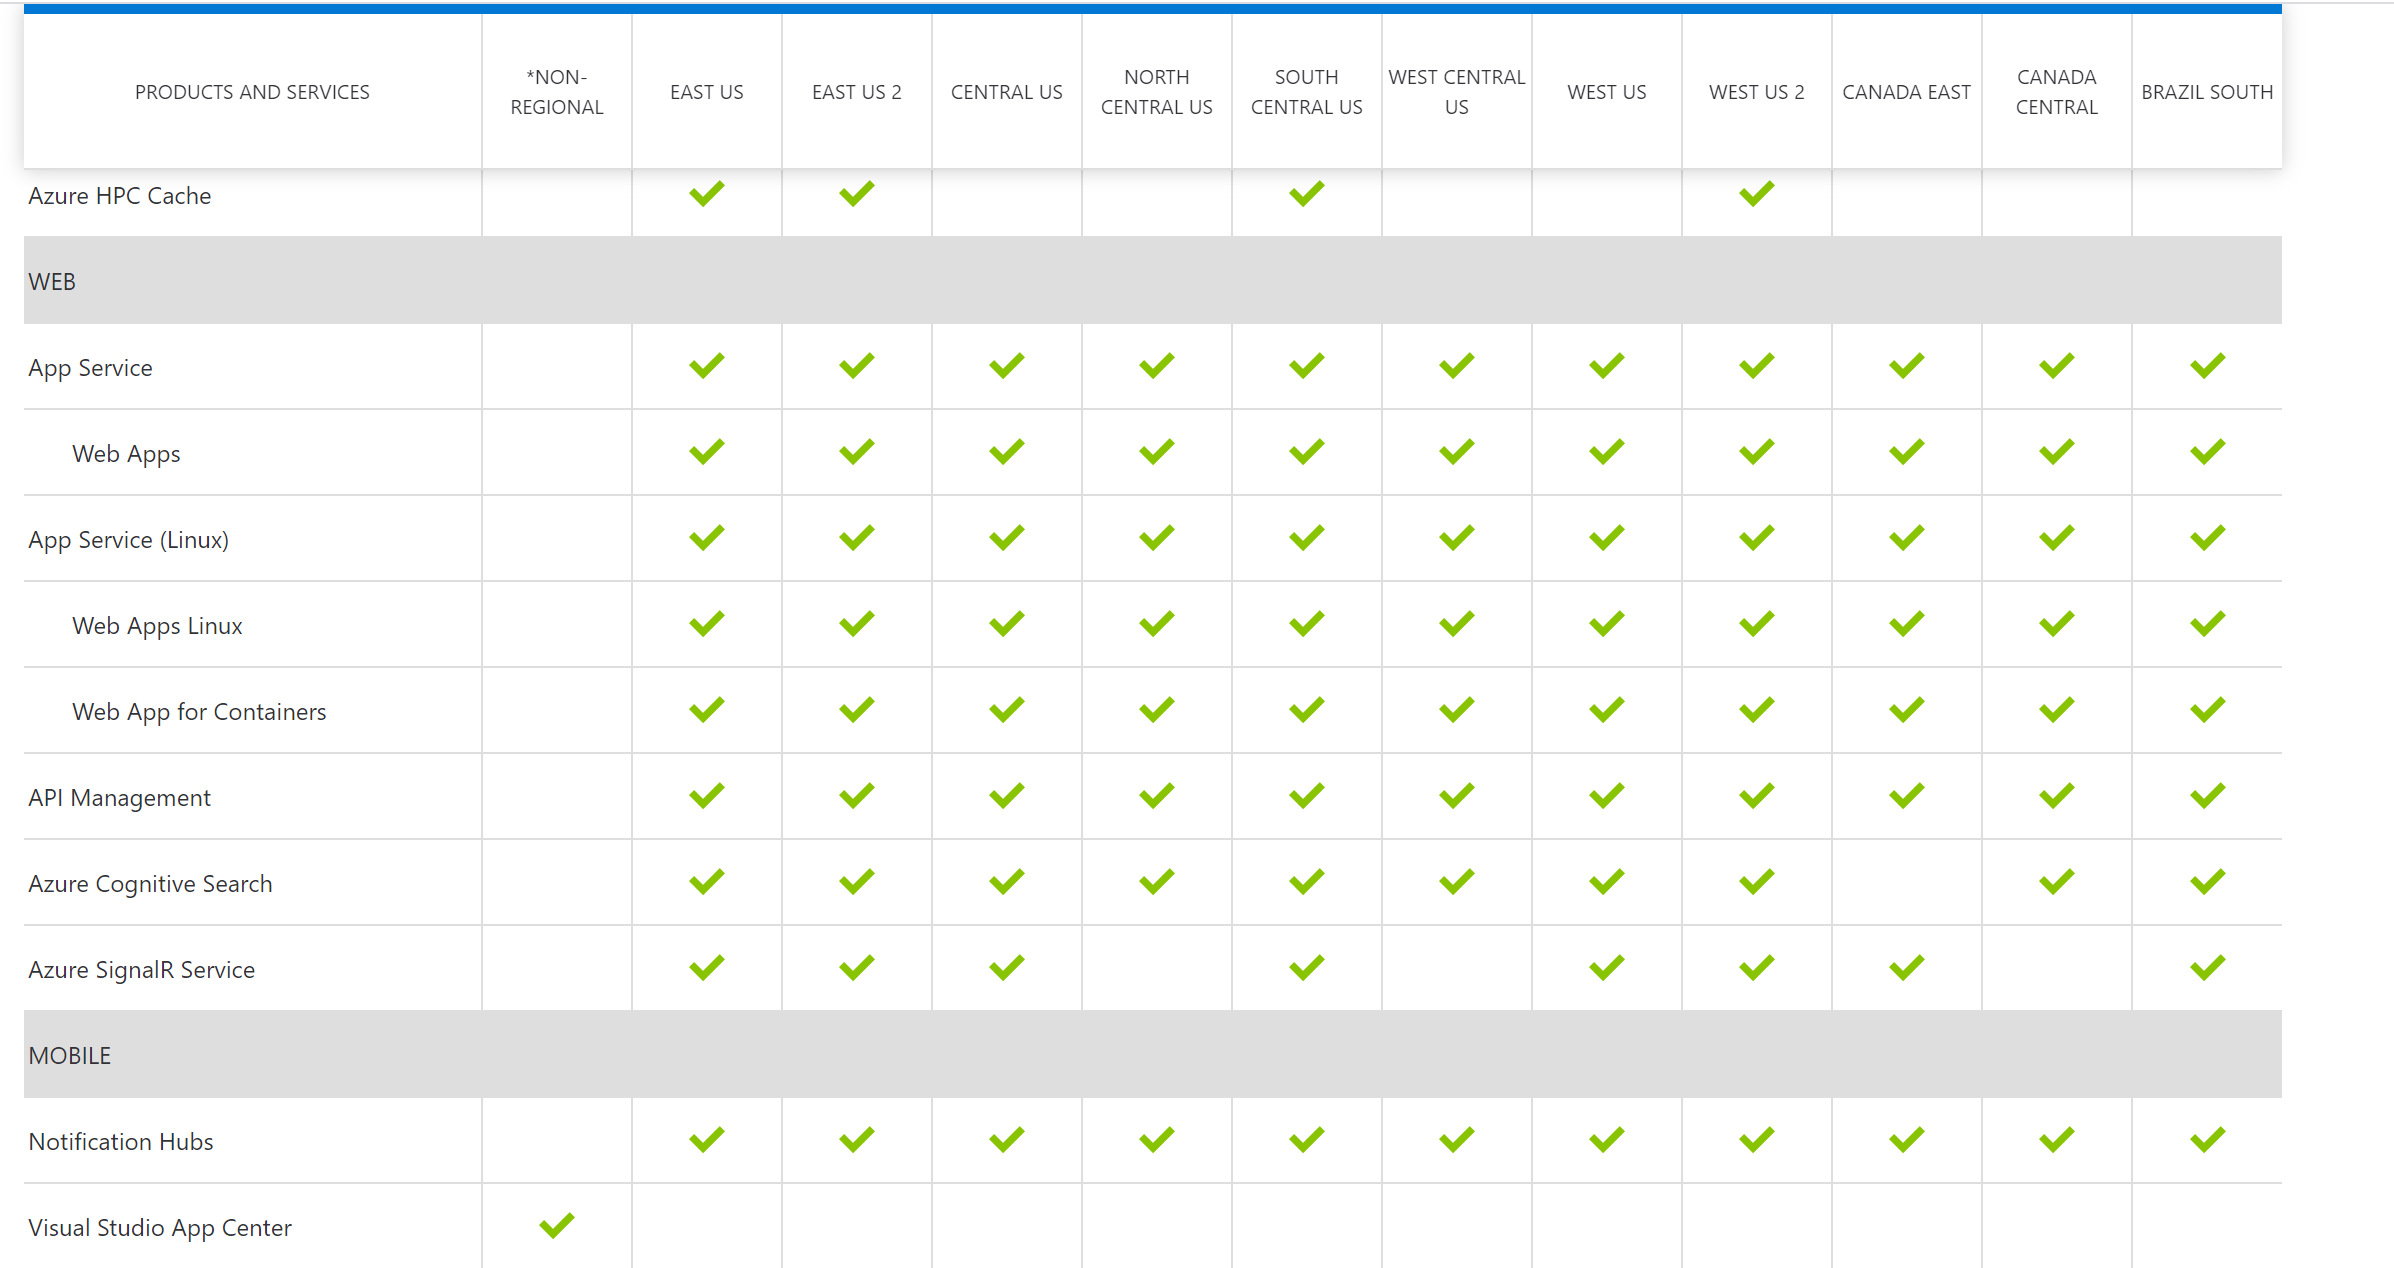
The public Azure Status page is the primary external-facing dashboard accessible to anyone via web browser without requiring an Azure subscription. It provides a global view of service health categorized by major product categories and geographic regions.
- Global Overview: Displays a map and status grid indicating whether core services are operating normally, experiencing performance degradation, or suffering a full outage.
- Incident History: Offers an archive of past incidents, including post-incident reviews (PIRs) and root cause analyses (RCAs) for major service interruptions.
- RSS and API Feeds: Allows teams to ingest real-time status updates directly into internal communication tools like Microsoft Teams, Slack, or ticketing systems via programmatic feeds.
Azure Service Health within the Azure Portal
For authenticated users managing active cloud environments, the Azure Service Health portal provides a personalized, resource-aware view of infrastructure health. Unlike the public dashboard, Service Health filters information specifically based on your deployed subscriptions, regions, and resource groups.
- Azure Service Health Components:
- Azure Status (Global/Regional broad events)
- Resource Health (Individual resource-level status)
- Planned Maintenance (Scheduled updates & security patches)
Within this portal, administrators can analyze three distinct pillars of cloud health:
- Azure Status: Broad notifications regarding regional service issues that may impact your deployed assets.
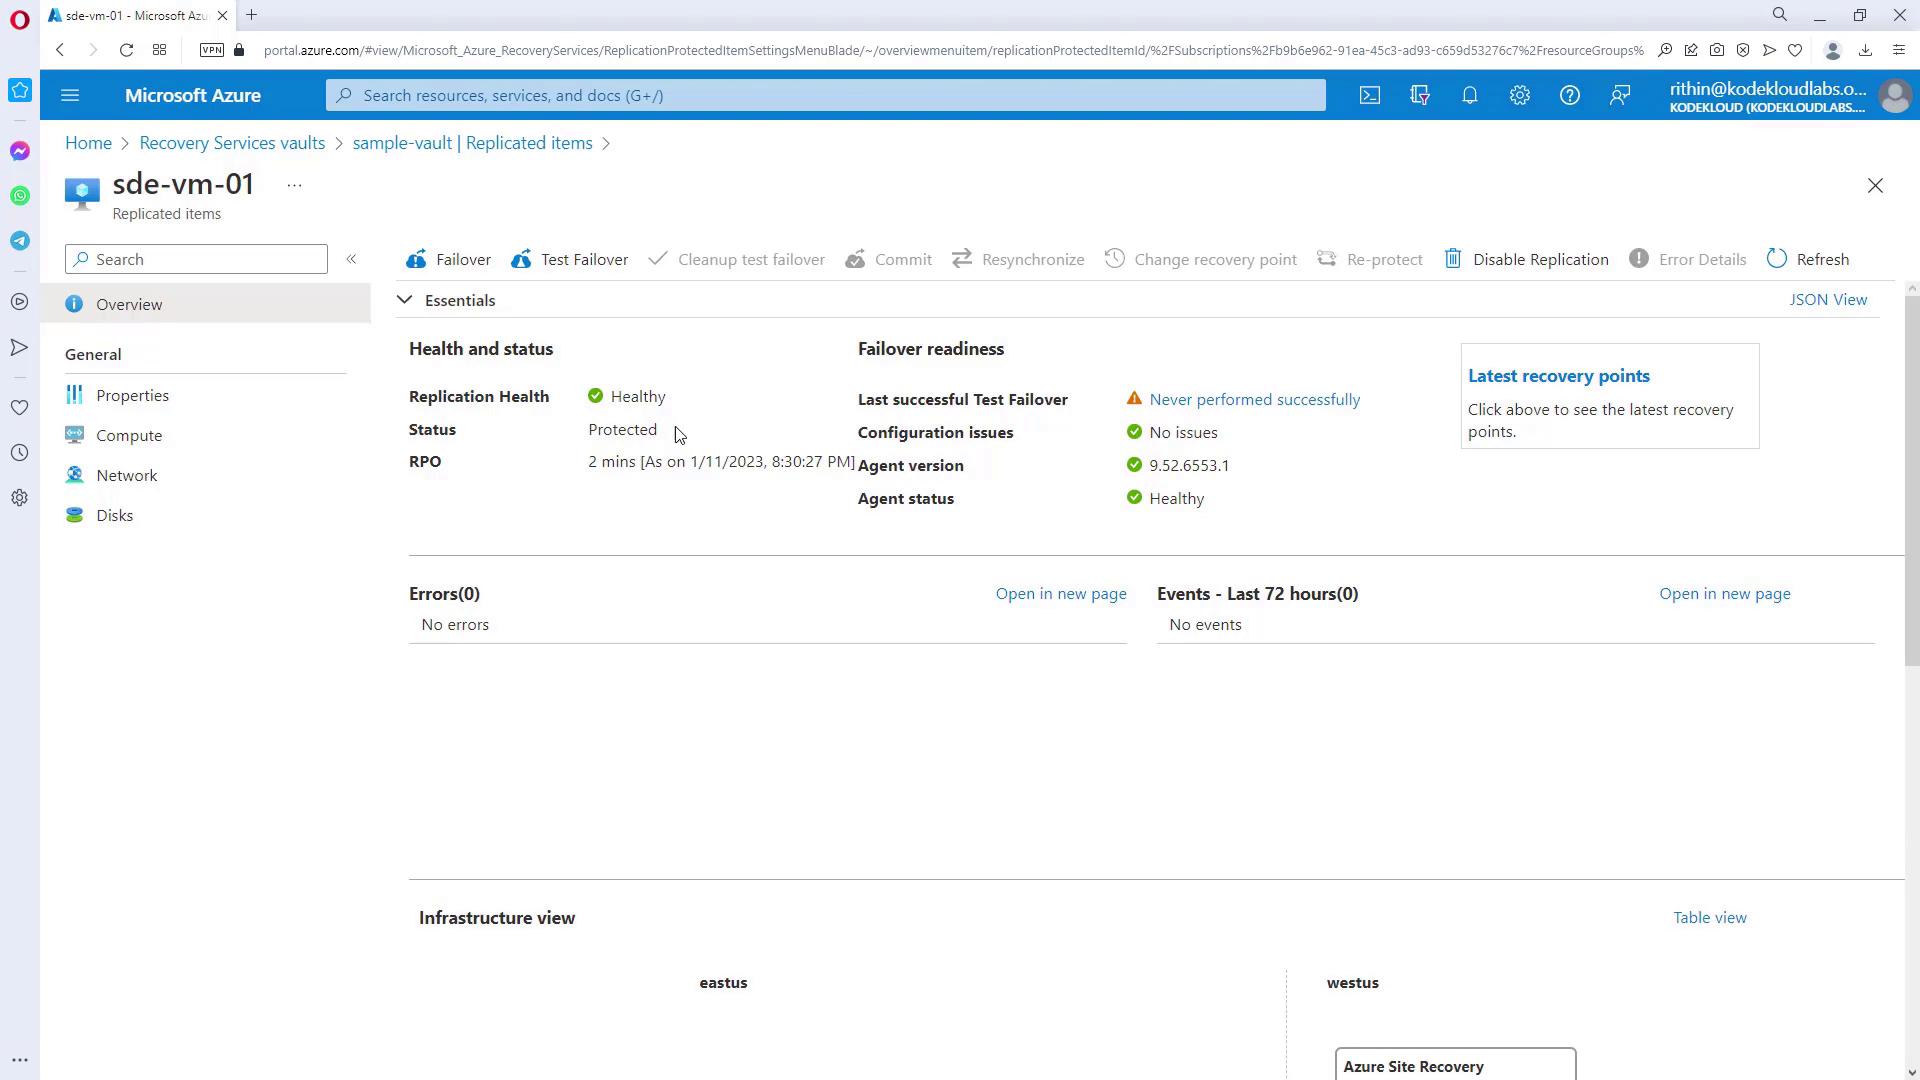
- Resource Health: Deep diagnostics indicating whether specific virtual machines, storage accounts, or web apps are healthy or experiencing platform-induced failures.
- Security Advisories: Notifications regarding potential security vulnerabilities, compliance alerts, or emergency patching mandates issued by Microsoft.
Core Components of Azure Health Monitoring
Effectively tracking Azure status requires distinguishing between broad regional incidents and granular resource-level failures. Misinterpreting the scope of an issue can lead to wasted troubleshooting efforts on application code when the underlying cloud fabric is experiencing a localized outage.
Regional Outages Versus Resource-Specific Issues
A regional outage occurs when an entire Azure region (such as East US or West Europe) encounters environmental, power, or core network failures, impacting multiple services within that boundary. These events are prominently featured on the public Azure status dashboard and trigger automated alerts in Service Health.
Conversely, a resource-specific issue affects only a single asset—such as a misconfigured network security group blocking traffic to a specific virtual machine or a database reaching its maximum storage capacity. Resource Health uses internal hypervisor telemetry to diagnose whether the host hardware running your specific virtual machine has failed, isolating the issue from your application logic.
Planned Maintenance and Security Advisories
Cloud providers frequently update host operating systems, hypervisors, and underlying storage hardware to improve performance and patch security vulnerabilities. Azure Service Health provides advance notification for these maintenance windows.
- Platform Updates: Inform administrators when virtual machines will undergo live migration or require reboots for host patching.
- Advisory Notifications: Highlight configuration recommendations or impending deprecations of specific API versions or database tiers.
Comparing Azure Health Monitoring Tools
Different stakeholders require different levels of detail when tracking cloud availability. The following comparison outlines the primary monitoring interfaces available within the Microsoft ecosystem.
| Monitoring Tool | Target Audience | Scope of Data | Accessibility | Best Used For |
|---|---|---|---|---|
| Public Azure Status Dashboard | Public, Executives, Clients | Global and regional service-level health | Web browser (No login required) | Quick verification of major, widespread cloud outages. |
| Azure Service Health (Portal) | IT Admins, DevOps Engineers | Subscription-specific resources and regions | Azure Portal (Authenticated) | Tracking infrastructure impacts specific to your organization. |
| Azure Monitor and Application Insights | Developers, SREs | Application-level performance and telemetry | Code instrumentation and portal | Monitoring custom app metrics, exceptions, and user traffic. |
| Azure Resource Health | System Administrators | Individual resource operational state | Azure Portal (Resource scoped) | Diagnosing whether a specific VM or database has failed. |
Setting Up Proactive Alerts for Azure Incidents
Waiting for users to report application failures is an inefficient operational strategy. Best practices dictate configuring automated alert rules within Azure Service Health to notify engineering teams immediately upon the declaration of a platform incident.
Configuring Action Groups and Notification Channels
Azure Monitor Action Groups define how notifications are delivered when an alert rule triggers. Administrators can configure multiple communication channels to ensure rapid incident response:
- Email and SMS: Direct alerts sent to on-call infrastructure engineers and incident managers.
- Webhook Integrations: Automated payloads sent to incident management platforms like PagerDuty, ServiceNow, or Opsgenie.
- ChatOps Integration: Automated alerts pushed directly into designated Microsoft Teams or Slack channels for collaborative troubleshooting.
Creating a Service Health Alert Rule
To establish robust monitoring, follow these structured steps to configure a subscription-level alert rule:
- Log in to the Azure Portal and navigate to Service Health.
- Select Service issues from the left-hand navigation menu.
- Click on Create service health alert to open the alert creation wizard.
- Define the Scope by selecting your target subscriptions, affected regions, and relevant service categories (e.g., Compute, Storage, Networking).
- Configure the Action Group by selecting existing notification recipients or creating a new group with your team's preferred communication endpoints.
- Provide an intuitive alert rule name and description, then click Create alert rule to finalize the configuration.
Troubleshooting Application Failures Versus Platform Outages
When an application hosted on Azure experiences latency spikes, HTTP 500 errors, or complete connection timeouts, engineers must systematically determine whether the root cause originates from application code or platform-level infrastructure degradation.
- Troubleshooting Workflow:
- Check Public Status Dashboard & Service Health -> Verify regional outages.
- Inspect Azure Resource Health -> Confirm individual VM/Database status.
- Review Azure Monitor Logs -> Analyze application exceptions and dependency failures.
- Execute Network Diagnostics -> Test DNS resolution, NSG rules, and routing paths.
Step 1: Verify Regional and Service Health
Begin by checking the public status page and the Service Health portal. If Microsoft has declared an active incident affecting the specific region or service your application relies on, further application-level debugging is often unnecessary until platform remediation is complete.
Step 2: Analyze Resource Health and Metrics
If no broad platform incidents are reported, examine Azure Resource Health for your specific virtual machines, load balancers, and databases. Review Azure Monitor metrics such as CPU percentage, disk latency, and network throughput to identify resource exhaustion.
Step 3: Inspect Application Logs and Traces
If infrastructure metrics appear normal, investigate application logs via Log Analytics workspaces or Application Insights. Look for database connection timeouts, unhandled exceptions in application code, or expired authentication certificates.
Frequently Asked Questions About Azure Status
How often is the public Azure status page updated?
The public Azure status page updates in near real-time as incidents are detected, triaged, and resolved by Microsoft incident response teams. For major events, communication cadence typically increases with regular status summaries until full mitigation is confirmed.
What is the difference between Azure Status and Azure Resource Health?
Azure Status provides a macro-level view of regional service health affecting all customers, whereas Azure Resource Health provides a micro-level, authenticated view of the specific operational state of individual resources deployed within your unique subscription.
Can I access Azure status programmatically via an API?
Yes. Microsoft provides the Azure Service Health REST API and Azure Resource Graph integrations, allowing organizations to programmatically query service incidents, planned maintenance schedules, and resource health states for integration into custom enterprise dashboards.
What should I do if my application is down but Azure status shows all green?
If platform status is normal, investigate application-level factors such as deployment errors, expired SSL certificates, misconfigured network security groups (NSGs), DNS propagation delays, or third-party API dependencies independent of Azure's infrastructure.
How are Service-Level Agreements (SLAs) affected by Azure outages?
Microsoft defines specific uptime SLAs for individual cloud services. If an outage breaches these defined availability thresholds, eligible customers may apply for service credit refunds in accordance with the official Azure Service-Level Agreements documentation.
Conclusion and Recommended Next Actions
Maintaining high availability in cloud environments requires continuous vigilance and proactive operational planning. Relying solely on manual checks of public dashboards is insufficient for enterprise-grade reliability. To ensure maximum operational readiness, administrators should immediately configure Service Health alert rules, integrate webhook notifications with incident response platforms, and establish clear internal runbooks for distinguishing between application-level errors and platform-level infrastructure outages.