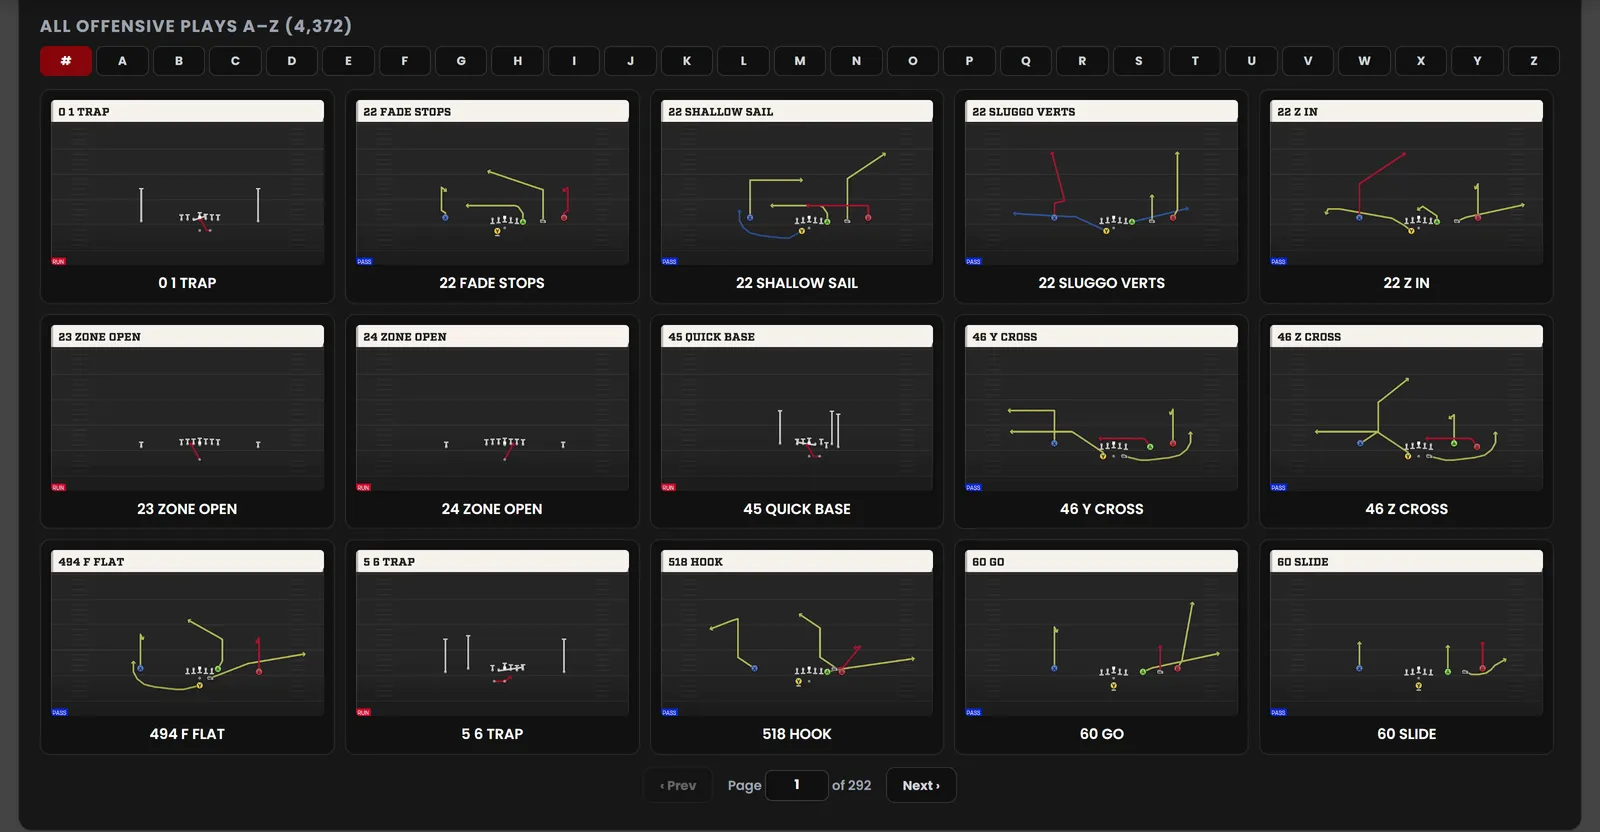
A college football (CFB) database is a centralized repository of historical, statistical, and operational records covering programs, players, games, and advanced metrics across collegiate divisions. These platforms serve sports journalists, fantasy football analysts, sports bettors, and dedicated researchers seeking structured data for predictive modeling, historical comparisons, and comprehensive game analysis.
Introduction to CFB Databases
The landscape of college football analysis has transformed dramatically over the past two decades. What once required manually tallying box scores from printed newspapers or tracking statistics in localized spreadsheets has evolved into a sophisticated discipline driven by robust data architectures. A modern college football database aggregates massive volumes of information—ranging from basic box scores and play-by-play logs to advanced analytics like Expected Points Added (EPA), Success Rate, and PFF (Pro Football Focus) player grades.
Navigating these databases requires an understanding of how data is structured, where it originates, and what access tiers are available. Whether you are building an independent prediction model, researching historical matchups for a publication, or tracking recruiting pipelines, choosing the right database dictates the speed, depth, and accuracy of your work. This guide explores the architecture of modern CFB databases, evaluates primary sources, outlines technical requirements for programmatic access, and highlights common challenges analysts face when processing collegiate sports data.
Understanding the Core Architecture of Sports Databases
To effectively utilize a college football database, one must first understand how raw athletic data is ingested, normalized, and stored. Unlike professional leagues such as the NFL, where data collection is heavily centralized and standardized by official league partners, college football encompasses hundreds of athletic departments operating across multiple governing bodies and conferences.
Data Ingestion and Normalization
The primary challenge of maintaining a comprehensive CFB database is ingestion. Data streams arrive from diverse sources:
- Official Feed Providers: Live game feeds provided by companies like Genius Sports or specialized athletic technology vendors.
- Play-by-Play Scrapers: Automated scripts that parse HTML or JSON endpoints from major sports networks (ESPN, Fox Sports, NCAA.com).
- Manual Entry: Historical archives requiring human verification for games played prior to the widespread adoption of digital play-by-play tracking.
Normalization is the process of translating these disparate inputs into a unified schema. For example, a player's name might be listed as "J. Smith" in one box score and "John Smith" in another. A robust database applies entity resolution algorithms to ensure unique identifiers (UUIDs) consistently tie to the correct individual, team, or venue across decades of records.
Relational vs. Non-Relational Storage
Most modern sports databases rely on relational database management systems (RDBMS) such as PostgreSQL or MySQL to maintain strict data integrity across interconnected tables. A typical relational schema includes:
- Teams Table: Metadata regarding universities, conferences, divisions, stadiums, and geographic locations.
- Players Table: Biographic details, positional designations, and career timelines.
- Games Table: Timestamps, home/away designations, weather conditions, attendance figures, and final scores.
- Plays Table: Granular, play-by-play breakdowns including down, distance, yard line, play type, penalty flags, and resulting yardage.
For unstructured data such as coaching playbooks, PDF game notes, or high-definition video clips, secondary document stores or cloud object storage buckets are frequently integrated alongside the primary database.
Major Public and Commercial CFB Data Providers
Depending on your use case—ranging from casual casual fan research to enterprise-level sports betting modeling—different databases offer distinct advantages in cost, depth, and accessibility.
1. CFBD (College Football Data)
Originally launched as an open-source project, the College Football Data API (formerly known as CollegeFootballData.com) has become a premier resource for independent analysts and sports data scientists.
- Key Features: Comprehensive historical play-by-play data, advanced metrics (EPA, success rates), recruiting rankings, transfer portal tracking, and betting lines.
- Access Method: REST API utilizing JSON responses, heavily integrated into Python libraries (
cfbd) for rapid data science workflows. - Cost: Free tiers available with API key registration; expanded access supported via community patronage platforms like Patreon.
2. Sports-Reference (College Football Reference)
For traditional statistical research, historical records, and draft history, Sports-Reference remains an industry standard.
- Key Features: Season-by-season team records, coaching ledgers, conference standings dating back to the 19th century, and detailed individual player career logs.
- Access Method: Web interface designed for human browsing, supplemented by table export utilities (CSV) and third-party web scrapers.
- Cost: Free public access supported by display advertising, with premium ad-free tiers available.
3. Pro Football Focus (PFF) College
PFF provides elite-level data focused on individual player performance grading rather than just box score outputs.
- Key Features: Offensive and defensive player grades, pass-blocking efficiency, coverage ratings, missed tackle counts, and specialized pressure metrics.
- Access Method: Subscription-based web dashboards and custom enterprise data feeds.
- Cost: Commercial pricing tailored for media outlets, professional front offices, and dedicated analytical firms.
Comparison of Popular CFB Data Solutions
| Database / Platform | Primary Focus | Access Method | Cost Model | Best Suited For |
|---|---|---|---|---|
| CFBD (College Football Data) | Advanced analytics, play-by-play, betting lines | REST API, Python Library | Free / Patronage | Data scientists, model builders, researchers |
| Sports-Reference | Historical records, traditional stats, drafting | Web, CSV Export | Free (Ad-supported) | Historians, journalists, casual fans |
| PFF College | Granular player grading, advanced scouting | Web Dashboard, Custom Feed | Paid Subscription | Professional scouts, advanced analysts, media |
| NCAA Statistics | Official governing body records, team leaders | Web Portal, Public PDFs | Free | Official compliance, baseline verification |
Technical Requirements for Programmatic Access
Accessing modern CFB databases programmatically requires a foundational understanding of web development and data science tooling. Whether you are querying an API or building a local SQLite database, certain technical prerequisites streamline the workflow.
API Authentication and Rate Limiting
Most active databases utilize RESTful APIs that require authentication via Bearer tokens or API keys passed in request headers. When designing scripts to pull multi-season datasets:
- Respect Rate Limits: APIs often enforce limits (e.g., 50 requests per minute) to prevent server degradation. Implement exponential backoff algorithms in your code to handle HTTP 429 (Too Many Requests) errors gracefully.
- Cache Responses: Save raw JSON or CSV payloads locally to avoid redundant network calls during development and testing phases.
Recommended Programming Stacks
Python is the undisputed language of choice for sports analytics due to its rich ecosystem of data manipulation and machine learning libraries:
- Pandas: Essential for cleaning, filtering, and reshaping tabular game data into structured dataframes.
- SQLAlchemy / Psycopg2: Used to connect Python environments directly to relational databases for long-term data persistence.
- Matplotlib / Seaborn / Plotly: Used to visualize trends, such as a team's offensive efficiency over the course of a multi-year coaching tenure.
Common Challenges in College Football Data Analysis
Working with collegiate athletic data introduces unique complications that professional sports leagues largely avoid. Analysts must account for these structural inconsistencies to maintain model accuracy.
Roster Turnover and Program Instability
Unlike the NFL, where rosters change incrementally via drafts and free agency, college football programs experience massive turnover annually due to graduation and the modern transfer portal. A database tracking a team's historical performance over five years may be analyzing entirely different player personnel from one season to the next, limiting the predictive power of pure player-level historical metrics.
Conference Realignment and Schedule Disparities
Conference structures shift frequently. A database must correctly handle historical changes—such as teams moving between Power Four conferences or independent status—without breaking historical queries. Furthermore, scheduling disparities (varying strength of schedule, FCS opponent matchups) require analysts to apply strength-of-schedule adjustments (SOS) to raw statistical outputs.
Data Inconsistencies in Historical Eras
While modern game data is tracked to the exact yard line with precise timestamping, games played prior to the 2000s often lack granular play-by-play logs. Analysts must be cautious when building predictive models that span multiple eras, ensuring that older, aggregated box-score data is not improperly weighed alongside modern advanced metrics.
Step-by-Step Guide: Building a Simple Local CFB Database
If you want to maintain your own lightweight database for personal modeling projects, follow these foundational steps using Python and SQLite.
- Environment Setup: Initialize a virtual environment and install necessary libraries (
pandas,requests,sqlite3is built into Python). - Endpoint Identification: Select a public data source (such as CFBD) and obtain a valid API key.
- Data Extraction: Write a script to fetch game results and team statistics for a specific season (e.g., 2025).
- Schema Definition: Create local SQL tables matching the expected data types (integers for scores, floats for advanced metrics, strings for team names).
- Data Insertion: Use Pandas to push cleaned dataframes directly into your SQLite database via
to_sql(). - Querying and Validation: Execute test queries to verify data integrity, such as calculating average yards per play for a specific conference.
Frequently Asked Questions
What is the most accurate CFB database for advanced analytics?
Platforms like College Football Data (CFBD) and PFF College are widely regarded as the most robust sources for advanced metrics. CFBD excels in play-by-play context, situational success rates, and EPA modeling, while PFF provides unmatched granularity in individual player performance grading.
Can I access historical college football data for free?
Yes. Sports-Reference provides free access to historical standings, player rosters, and traditional box scores dating back over a century. Additionally, CFBD offers robust free-tier API access for developers and independent researchers.
How do modern databases handle the NCAA transfer portal?
Advanced CFB databases maintain dedicated tracking tables that log player entry into the transfer portal, subsequent commitments, and roster updates. This data is linked via unique player IDs to maintain career statistics across multiple institutions.
Are betting lines and odds included in CFB databases?
Many modern databases, including CFBD, ingest historical betting lines (spreads, over/unders, moneylines) from major sportsbooks. This allows quantitative analysts to backtest predictive models against historical closing lines.
What technical skills are needed to query a CFB API?
Basic proficiency in Python or R is highly recommended. Familiarity with RESTful APIs, JSON data parsing, and SQL relational databases will allow you to efficiently pull, clean, and analyze collegiate football datasets.
Conclusion and Next Actions
Accessing and utilizing a college football database opens up immense opportunities for researchers, journalists, and sports fans alike. Whether you choose to leverage existing web dashboards like Sports-Reference or build automated analytical pipelines using API-driven resources like CFBD, understanding data normalization, schema design, and analytical limitations is paramount. To begin your journey, register for a developer API key with an open-source provider, establish a local SQLite environment, and start by analyzing a single conference season to test your data ingestion workflows.