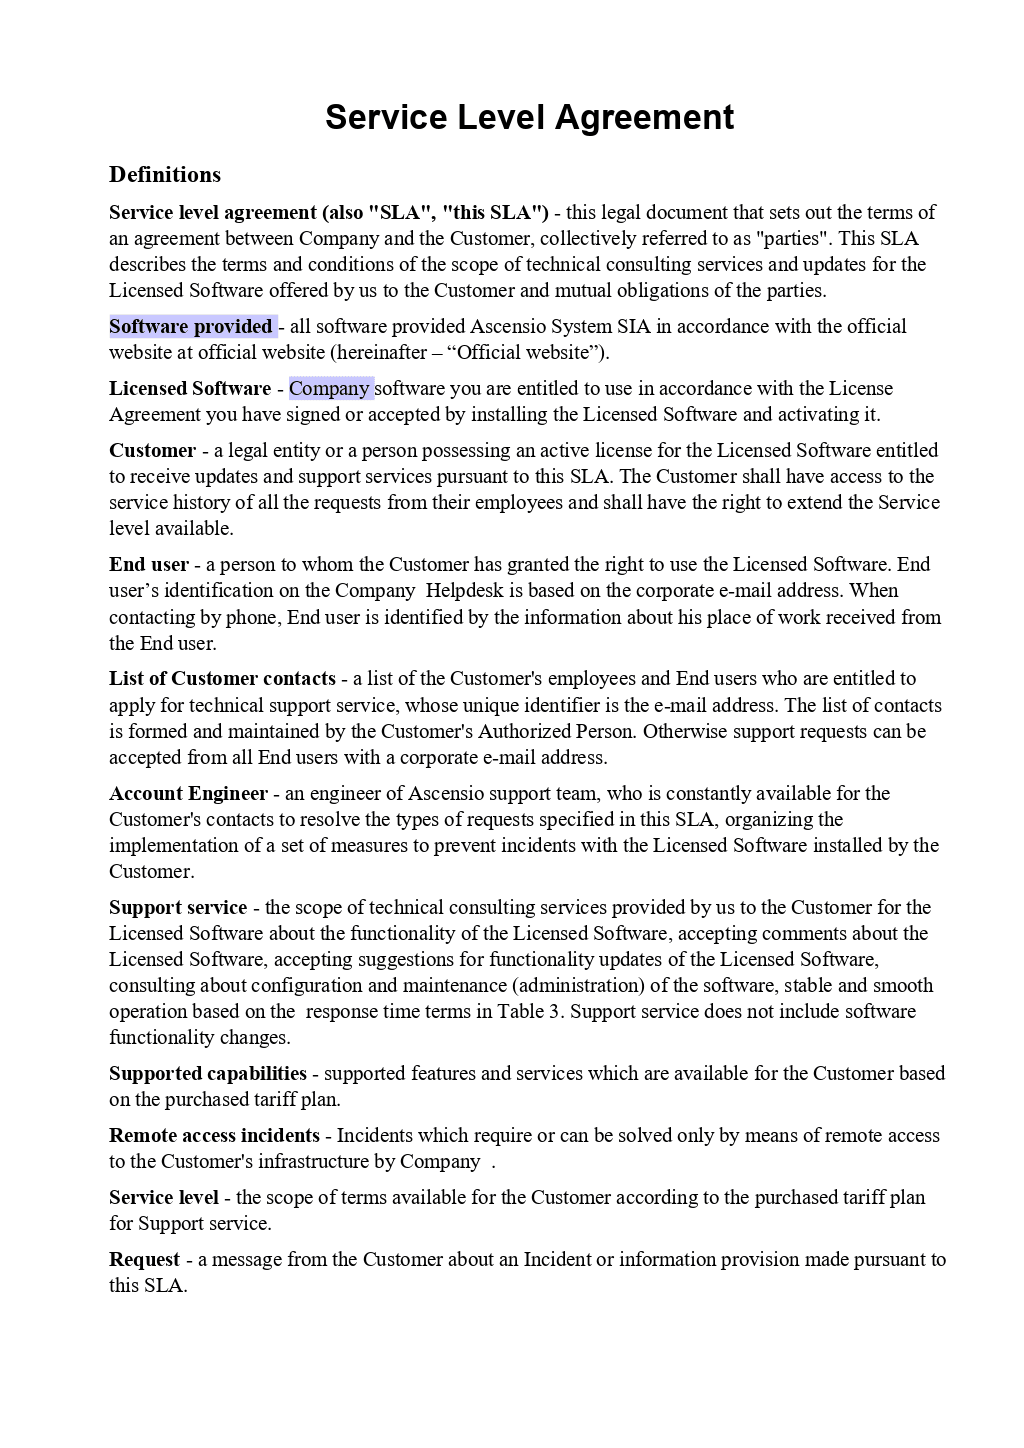
A Service Level Agreement (SLA) is a formal contract between a service provider and a customer that specifies the minimum standards for service quality, availability, and responsibilities. It defines measurable metrics, such as uptime or response times, and outlines the remedies or penalties if these agreed-upon standards are not met.
Service Level Agreements serve as the foundational blueprint for the relationship between a vendor and a client. In an era where digital infrastructure and third-party services drive the global economy, the SLA acts as a safeguard, ensuring that expectations are aligned and that there is a clear path for recourse when performance falters. Whether you are a business purchasing a Cloud-based software solution or an internal IT department providing services to other business units, understanding the nuances of an SLA is critical for operational stability.
The Core Components of a Service Level Agreement
An effective SLA is not merely a statement of intent; it is a granular document that breaks down service delivery into quantifiable segments. To be legally and operationally sound in 2026, an SLA must move beyond vague promises and into the territory of strict, data-driven parameters.
Service Description and Scope
The first pillar of any SLA is a detailed description of the services provided. This includes every functional component of the service, from software access and hardware maintenance to customer support availability. It must explicitly state what is included and, perhaps more importantly, what is excluded. Without a defined scope, "scope creep" can lead to disputes where the customer expects support for a third-party integration that the provider never intended to cover.
Performance Metrics and Benchmarks
Metrics are the heart of the SLA. These are the Key Performance Indicators (KPIs) that determine whether the provider is fulfilling their end of the bargain. Common metrics include:
- Availability (Uptime): Often expressed as a percentage, such as 99.9% or 99.999%.
- Latency: The time it takes for a data packet to travel from one point to another.
- Throughput: The amount of data processed within a specific timeframe.
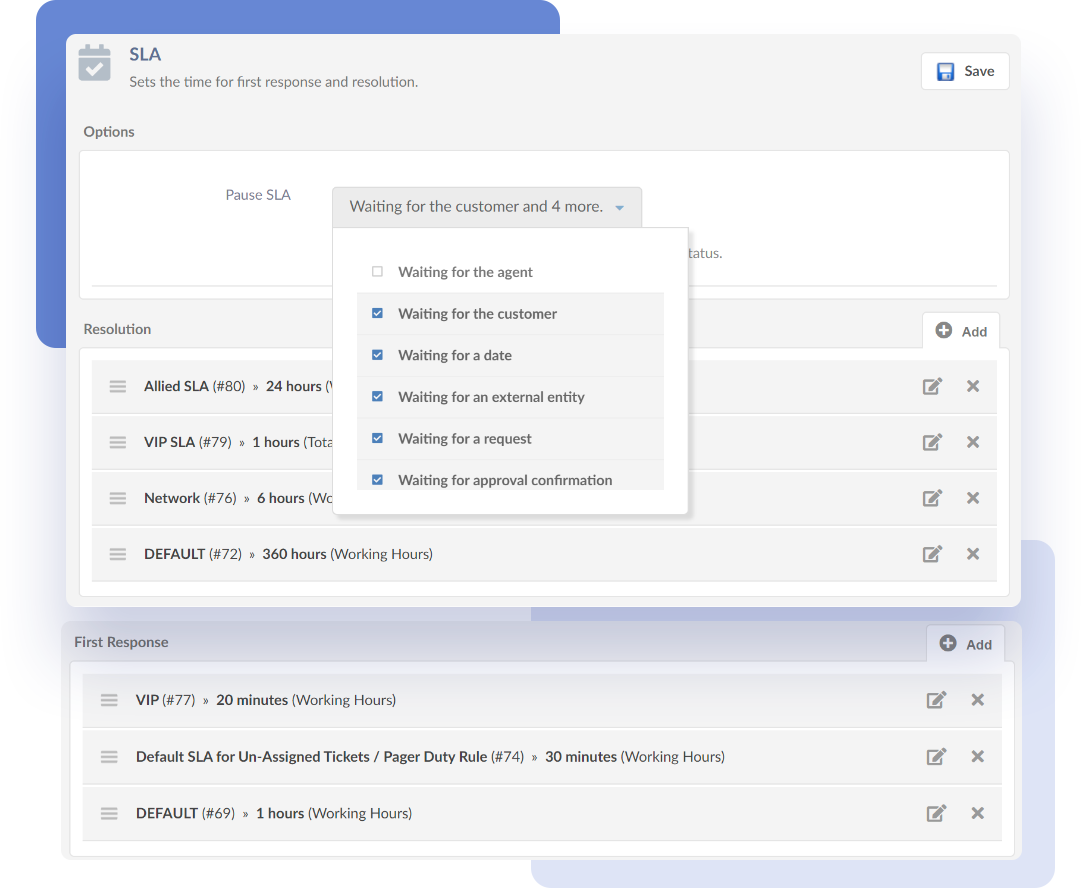
- Response Time: How quickly the provider acknowledges a support ticket.
- Resolution Time: How long it takes to actually fix a reported issue.
Duties and Responsibilities
An SLA is a two-way street. While it focuses heavily on the provider, it must also outline the customer's obligations. For instance, if a server goes down because the customer failed to provide the necessary administrative access to the provider, the provider should not be held liable for the breach of uptime. Clearly defining these dependencies prevents one party from being unfairly penalized for the other’s negligence.
Penalties and Service Credits
If a provider fails to meet the agreed-upon levels, there must be a consequence. In most commercial SLAs, this takes the form of service credits. If the uptime drops below the threshold, the customer might receive a 5% or 10% discount on their next monthly bill. In high-stakes environments, such as financial trading platforms, these penalties might also include the right to terminate the contract without notice or penalty.
The Evolution of SLA Metrics: SLOs and SLIs
To fully grasp the meaning of an SLA in a modern technical context, one must distinguish between three closely related terms that are often used interchangeably but have distinct roles: SLIs, SLOs, and SLAs.
Service Level Indicators (SLI)
An SLI is the actual measurement of a specific aspect of a service. If you are measuring uptime, the SLI is the specific data point—for example, "the system was available 99.95% of the time last month." It is the raw data that informs the higher-level agreements.
Service Level Objectives (SLO)
An SLO is the target value or range of values for a service level that is measured by an SLI. While the SLA is the legal agreement with the customer, the SLO is the internal goal the technical team strives for. Often, internal SLOs are stricter than the public-facing SLA. If the SLA promises 99.9% uptime, the internal SLO might be 99.95% to provide a "safety buffer" or an "error budget."
Error Budgets
The concept of an error budget is a 2026 industry standard for managing the tension between system reliability and the need for rapid innovation. An error budget is the amount of downtime or "unreliability" a service can tolerate before it violates its SLO. If a team has a 99.9% SLO, they have an error budget of 0.1%. If they use up that budget due to failed updates or outages, they must halt all new feature releases and focus entirely on stability until the budget is replenished.
Different Types of Service Level Agreements
Not all SLAs are structured the same way. The architecture of the agreement depends heavily on the relationship between the parties and the nature of the service.
1. Customer-Based SLA
This is an agreement between a service provider and an individual customer group. It covers all the services used by that specific customer. For example, a large enterprise might have a single SLA with an IT provider that covers their email, CRM system, and cloud storage under one umbrella agreement tailored to that enterprise’s specific needs.
2. Service-Based SLA
In this model, the agreement is identical for all customers using a specific service. If you sign up for a public cloud provider like AWS or Microsoft Azure, you are typically agreeing to a service-based SLA. Every user of the "Standard Storage Tier" gets the same uptime guarantees, regardless of who they are.
3. Multi-Level SLA
Large organizations often use multi-level SLAs to avoid redundancy. This structure might have a Corporate Level (applying to all users in the organization), a Customer Level (specific to a department), and a Service Level (specific to a particular software tool). This allows the organization to set a baseline of expectations while allowing for "tighter" requirements for mission-critical departments, like the security operations center.
Critical Performance Standards: Comparing the "Nines"
The most common way to measure the quality of an SLA is through the "number of nines" in the uptime percentage. While the difference between 99% and 99.99% might seem negligible on paper, the real-world impact on downtime is massive.
| Uptime Percentage | Daily Downtime | Monthly Downtime | Annual Downtime |
|---|---|---|---|
| 99% ("Two Nines") | 14.4 minutes | 7.31 hours | 3.65 days |
| 99.9% ("Three Nines") | 1.44 minutes | 43.83 minutes | 8.77 hours |
| 99.95% ("Three and a half") | 43.2 seconds | 21.92 minutes | 4.38 hours |
| 99.99% ("Four Nines") | 8.64 seconds | 4.38 minutes | 52.60 minutes |
| 99.999% ("Five Nines") | 0.86 seconds | 26.30 seconds | 5.26 minutes |
In 2026, 99.9% is considered the baseline for standard business applications. However, for critical infrastructure, telecommunications, and financial services, 99.999% is the industry gold standard. Achieving "Five Nines" requires significant investment in redundancy, automated failovers, and rigorous disaster recovery protocols.
The Role of Exclusions and Force Majeure
A common mistake when reviewing an SLA meaning is ignoring what happens during "extraordinary circumstances." No provider can guarantee 100% uptime because there are factors outside their control.
Scheduled Maintenance
Almost every SLA includes a clause for scheduled maintenance. These windows, usually occurring during off-peak hours (e.g., Sunday at 2:00 AM), do not count toward the "downtime" calculations. However, the provider is usually required to give a specific notice period (such as 48 or 72 hours) before the maintenance begins.
Force Majeure
This legal term refers to "acts of God" or events that are unforeseeable and unavoidable, such as earthquakes, floods, or global political instability. If a data center is destroyed by a natural disaster, the provider is generally not liable for the resulting breach of the SLA.
Customer-Induced Issues
If the customer misconfigures their firewall or accidentally deletes their own database, the provider is not responsible. Modern SLAs are becoming increasingly specific about the "demarcation point"—the exact point where the provider’s responsibility ends and the customer’s begins.
Legal and Financial Implications of SLA Breaches
When a breach occurs, the process for claiming compensation is rarely automatic. It requires a structured approach to documentation and communication.
- Detection and Logging: The customer must have their own monitoring tools to verify the provider’s claims. If the provider’s dashboard says "all systems green" but the customer cannot access the service, the customer needs their own logs to prove the outage.
- Notification: Most SLAs require the customer to notify the provider within a certain timeframe (e.g., 24 hours) of detecting a breach. Failure to report the issue promptly can result in a forfeiture of service credits.
- Credit Calculation: Once the breach is verified, credits are calculated as a percentage of the monthly service fee. It is important to note that service credits are usually the "sole and exclusive remedy" for an SLA breach, meaning the customer cannot sue for additional damages unless there was gross negligence.
Best Practices for Negotiating an SLA in 2026
If you are in a position to negotiate an SLA, whether as a buyer or a provider, keep these strategic considerations in mind:
- Align Metrics with Business Goals: Don't just ask for "high uptime" because it sounds good. If your business only operates from 8 AM to 6 PM, a 99.99% uptime guarantee for 24/7 access might be an unnecessary expense. Focus on the metrics that actually impact your bottom line.
- Insist on Real-Time Reporting: In the current technological landscape, waiting for a monthly report is no longer acceptable. Demand access to a real-time dashboard where you can see the SLIs as they happen.
- Define "Severity Levels": Not all problems are created equal. A total system outage (Severity 1) should have a much faster response time requirement than a cosmetic bug in the user interface (Severity 4).
- Review Termination Rights: If a provider consistently fails to meet their SLA targets over a three-to-six-month period, you should have the right to terminate the contract for cause without paying an early termination fee.
Common Pitfalls to Avoid
Even with the best intentions, SLAs can fail if they are poorly drafted.
- Vague Definitions: Phrases like "reasonable efforts" or "standard business hours" are invitations for disagreement. Every term must be defined with numbers and specific time zones.
- Over-Complexity: An SLA that is 50 pages long with hundreds of metrics is impossible to manage. It is better to have five meaningful, enforceable metrics than fifty that are ignored.
- Lack of Review: An SLA should be a living document. As technology changes and your business scales, the agreement you signed three years ago may no longer be relevant. Annual or biennial reviews are essential.
Frequently Asked Questions
What happens if an SLA is not met?
When a provider fails to meet an SLA, the primary remedy is typically the issuance of service credits. These credits are applied to the customer's future invoices, reducing the total cost. In cases of chronic failure or severe breaches, the customer may also have the right to terminate the contract. It is rare for SLAs to provide direct cash refunds; the compensation is almost always in the form of discounted future service.
Is an SLA the same as a contract?
An SLA is a part of a larger legal contract. While the main contract (often called a Master Service Agreement or MSA) covers the general legal terms like payment, intellectual property, and liability, the SLA is the specific technical annex that defines the performance expectations and service quality. You cannot have an effective SLA without the legal framework of an MSA to support it.
What is a "reasonable" uptime percentage?
For most non-critical business applications, 99.9% (Three Nines) is considered a reasonable and standard uptime. This allows for about 43 minutes of unscheduled downtime per month. However, for mission-critical services like payment gateways or emergency communication systems, anything less than 99.99% (Four Nines) or 99.999% (Five Nines) may be considered inadequate.
Who is responsible for monitoring SLA compliance?
Both the provider and the customer should monitor compliance. While the provider usually maintains the "official" record of uptime and performance, a diligent customer will use third-party monitoring tools to verify these claims. In the event of a dispute, having independent, third-party data is crucial for the customer to successfully claim service credits.
Can internal departments have SLAs?
Yes, these are known as Operational Level Agreements (OLAs). An OLA functions exactly like an SLA but exists between two departments within the same company. For example, the IT department might have an OLA with the Sales department, guaranteeing that the CRM system will be available during business hours and that password reset requests will be handled within two hours.
Practical Recommendation: Next Steps
To ensure your organization is protected by its Service Level Agreements, perform an immediate audit of your existing contracts. Start by identifying your most "mission-critical" vendors—those whose failure would stop your business operations. Review their current uptime and response time commitments. If those metrics are not clearly defined, or if the "remedies" for failure are non-existent, initiate a contract renegotiation. For new vendors, never accept a boilerplate SLA without first ensuring that the metrics align with your specific operational hours and business risks.