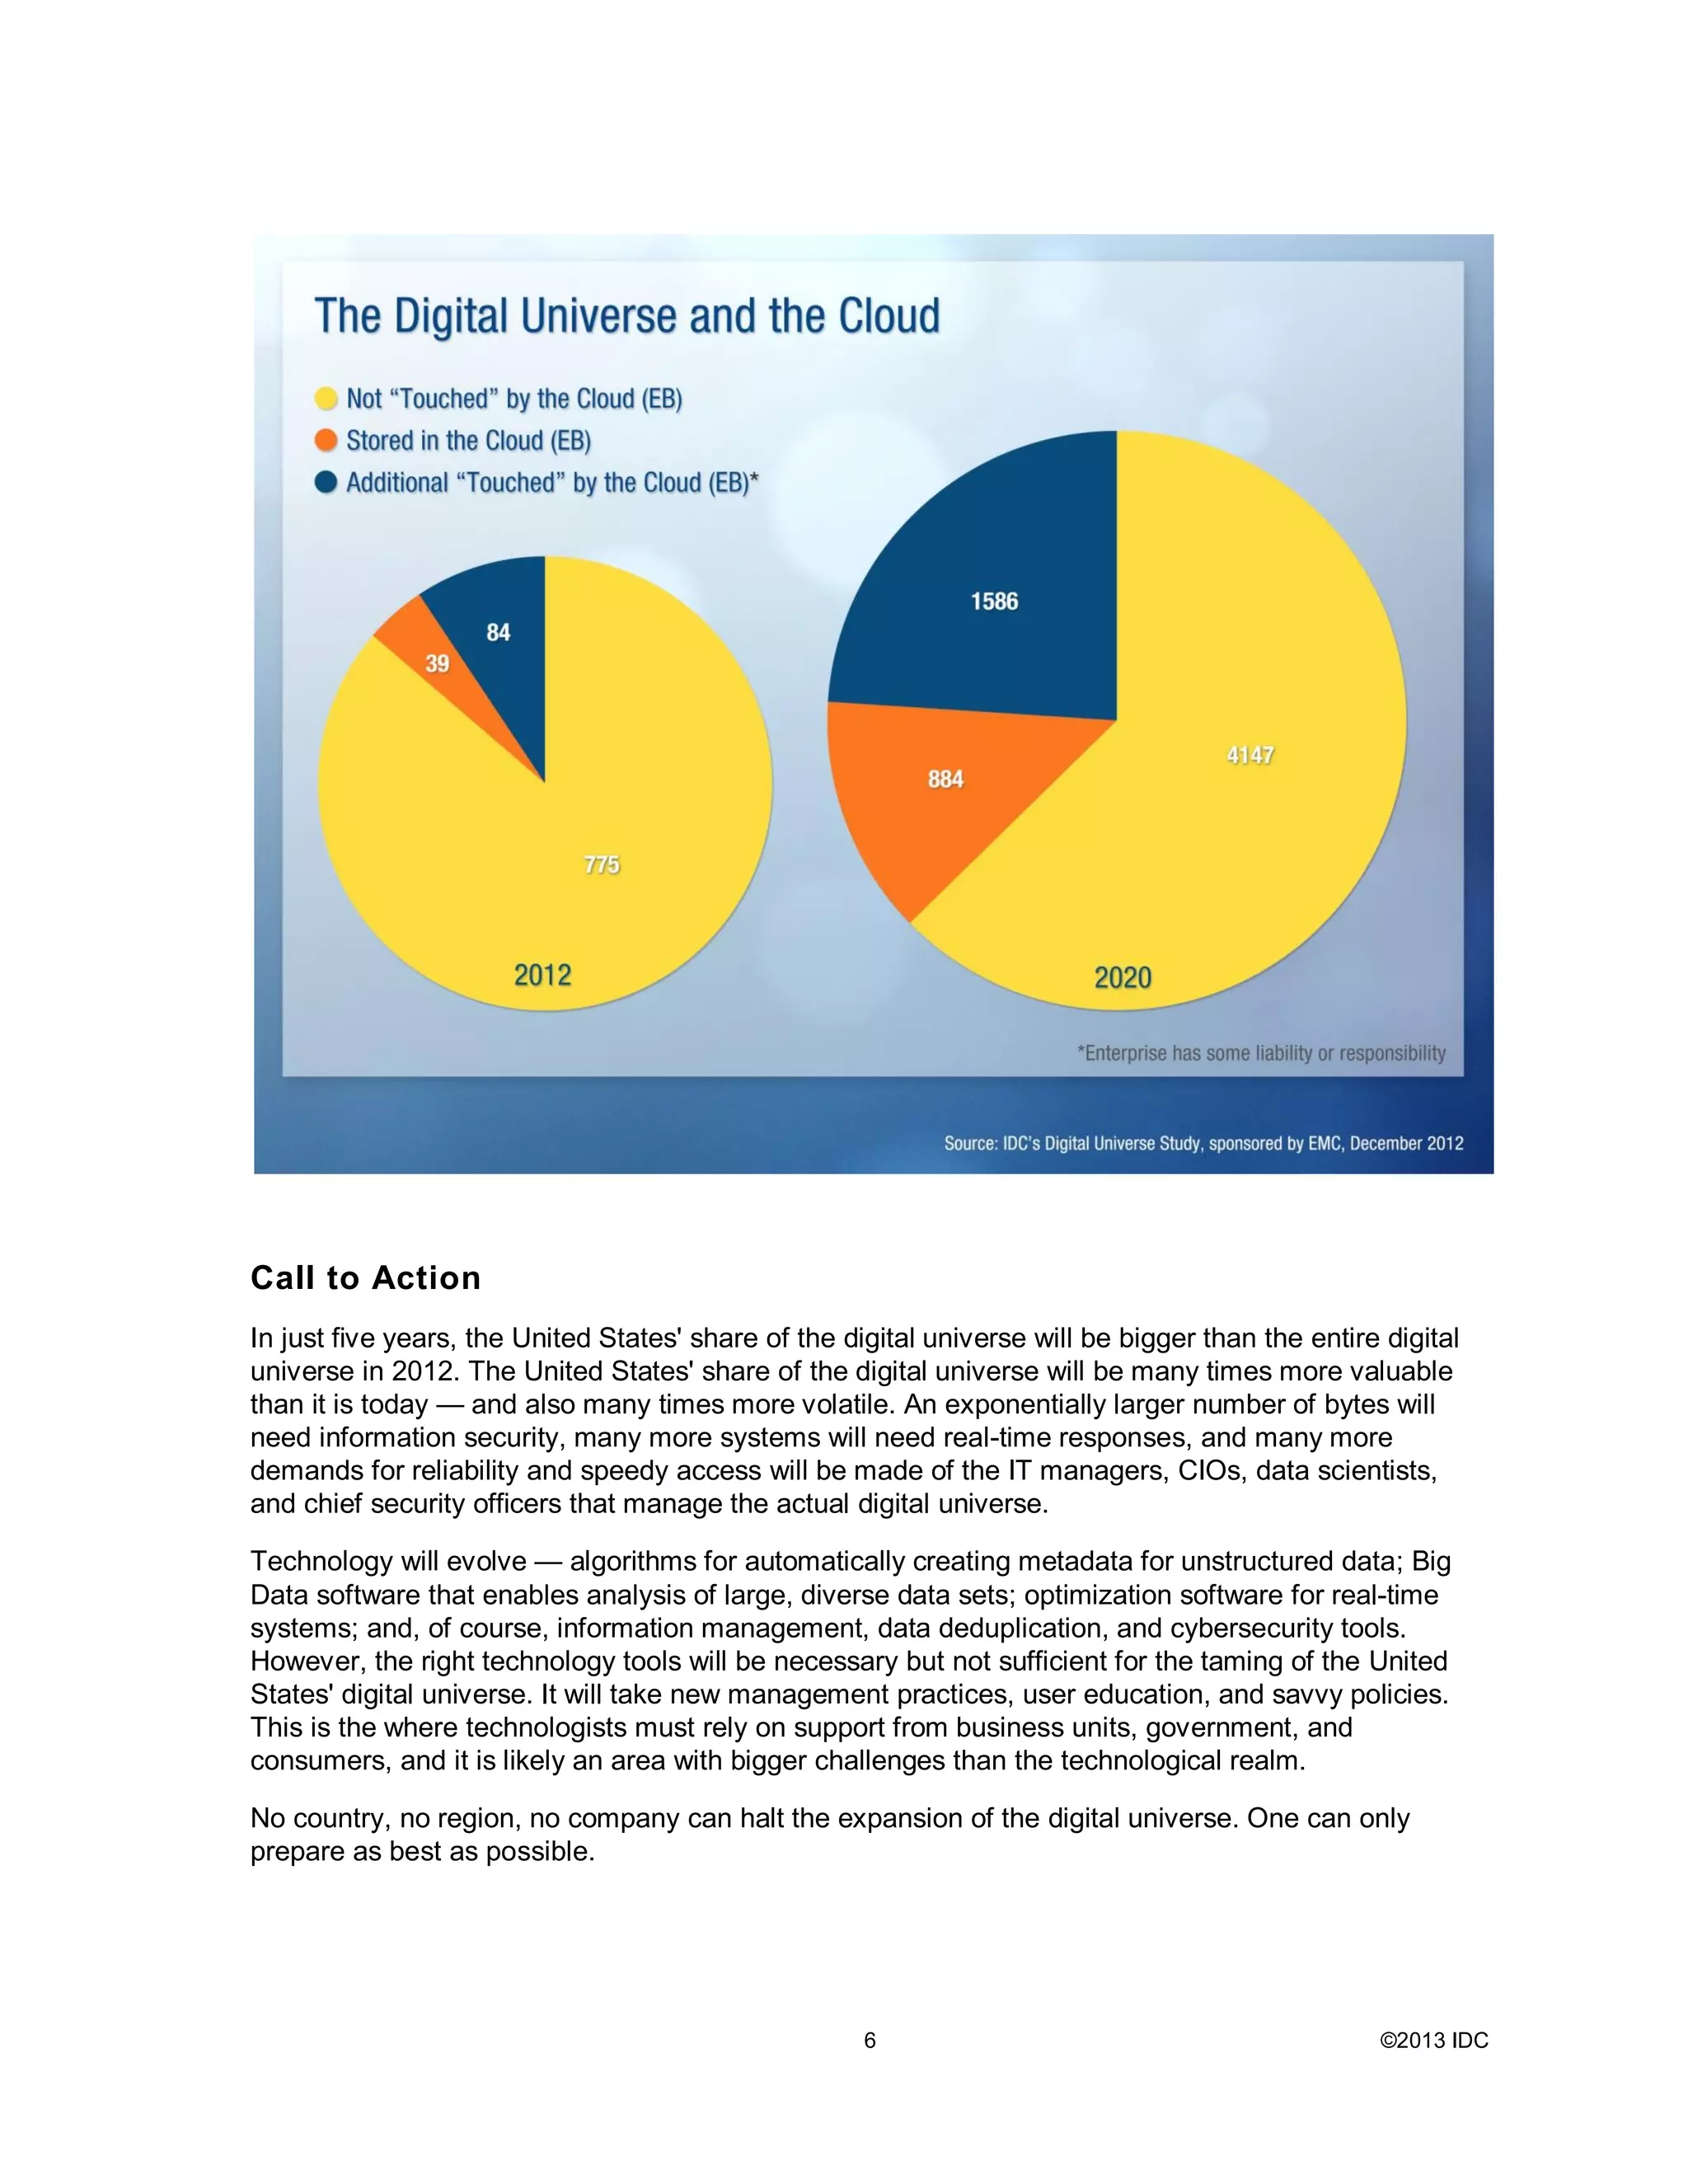
The data universe refers to the sprawling ecosystem of digital information, storage repositories, analytics tools, and governance frameworks that organizations use to capture, process, and leverage information. It encompasses everything from operational databases and cloud data lakes to machine learning pipelines, structured records, and unstructured files spread across hybrid enterprise environments.
Understanding the Data Universe
Modern organizations face an unprecedented expansion of digital information. The term "data universe" serves as a conceptual and architectural framework to make sense of this complexity. Rather than viewing data as isolated tables in a single database, architects and data engineers treat information as an interconnected ecosystem. This ecosystem spans multiple cloud providers, on-premises servers, edge devices, and third-party software-as-a-service (SaaS) applications.
At its core, the data universe model shifts focus from mere storage to holistic lifecycle management. Information is continuously ingested, transformed, stored, analyzed, and eventually archived or purged. Understanding this lifecycle is essential for organizations seeking to derive actionable intelligence without drowning in noise, security vulnerabilities, and exorbitant storage costs.
Key Characteristics of Modern Information Ecosystems
The modern information landscape differs fundamentally from the rigid data warehousing models of the late 20th century. Several defining traits characterize this shift:
- Massive Volume and Velocity: Information arrives continuously from user interactions, Internet of Things (IoT) sensors, financial transactions, and system logs, often requiring real-time stream processing.
- Extreme Variety: Traditional relational databases handled neat rows and columns. Today’s ecosystem accommodates unstructured text, video feeds, audio files, geospatial data, and semi-structured formats like JSON and XML.
- Distributed Storage: Data rarely lives in a single data center. Multi-cloud strategies involving Amazon Web Services (AWS), Microsoft Azure, and Google Cloud Platform (GCP) distribute assets globally.
- Democratization: Analytics and data manipulation are no longer restricted to specialized database administrators. Business intelligence tools empower non-technical stakeholders to query and visualize information independently.
Core Architectural Components
Building a resilient data universe requires a well-defined architecture that connects raw input to polished insight. Organizations typically deploy a multi-layered stack designed to handle ingestion, storage, processing, and consumption.
[ Data Sources ] ---> [ Ingestion Layer ] ---> [ Storage Layer (Lake/Warehouse) ] ---> [ Processing & Transformation ] ---> [ Consumption Layer (BI/ML) ]
1. Ingestion and Integration Layer
Before data can be analyzed, it must enter the ecosystem. The ingestion layer handles batch transfers and real-time streaming using tools like Apache Kafka, AWS Kinesis, or specialized ETL (Extract, Transform, Load) platforms such as Fivetran and Airbyte. This layer ensures that information originating from disparate APIs, relational databases, and clickstream trackers is reliably transported to central repositories.
2. Storage Layer: Data Lakes, Warehouses, and Lakehouses
Storage strategies have evolved to balance cost, flexibility, and performance.
- Data Lakes: Cost-effective repositories that store raw data in its native format (structured or unstructured) using object storage like Amazon S3 or Azure Blob Storage.
- Data Warehouses: Highly structured, optimized relational environments (such as Snowflake, Google BigQuery, or Amazon Redshift) designed for high-performance analytical queries and reporting.
- Lakehouses: Emerging architectural patterns that combine the flexible storage of data lakes with the ACID transactions and governance of data warehouses.
3. Processing and Transformation Engine
Raw data is rarely ready for analysis. Transformation engines, powered by frameworks like Apache Spark, dbt (data build tool), and SQL-based orchestration pipelines, clean, normalize, and model information into business-ready schemas. This ensures consistency across reporting dashboards and machine learning models.
4. Consumption and Analytics Layer
The final layer translates processed data into human-readable insights or machine-driven actions. This includes business intelligence (BI) platforms like Tableau, Power BI, and Looker, as well as machine learning feature stores that feed predictive models built in Python or R.
Data Governance, Security, and Compliance
As the data universe expands, the risks associated with mismanagement multiply. Effective governance is the anchor that prevents an enterprise data strategy from collapsing under regulatory fines, data breaches, and poor data quality.
Data Quality and Observability
Garbage in equals garbage out. Modern data stacks incorporate automated data observability tools to monitor pipeline health, schema changes, and data anomalies. If a third-party API alters its output format or a pipeline fails mid-stream, data observability platforms alert engineering teams before faulty data corrupts downstream executive dashboards.
Privacy Regulations and Compliance
Organizations must navigate an increasingly stringent global regulatory landscape. Regulations such as the European Union's General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA) grant consumers strict rights regarding data access, correction, and deletion ("the right to be forgotten"). Compliance requires comprehensive data lineage tracking—the ability to trace any piece of information back to its origin and identify every system where it is replicated.
Access Control and Security
A secure data universe implements the principle of least privilege. Role-Based Access Control (RBAC) and Attribute-Based Access Control (ABAC) ensure that employees only access data necessary for their specific roles. Encryption at rest and in transit, combined with robust tokenization and masking protocols, protects sensitive customer information from unauthorized exposure.
Comparing Storage Paradigms in the Data Universe
Choosing the right storage architecture depends on cost, performance requirements, and data variety. The table below compares the three primary storage paradigms found in modern enterprise architectures.
| Feature / Metric | Data Lake | Data Warehouse | Data Lakehouse |
|---|---|---|---|
| Primary Data Types | Unstructured, semi-structured, structured | Structured, highly cleaned tabular data | Unstructured, semi-structured, and structured |
| Storage Cost | Low (object storage pricing) | High (optimized proprietary storage) | Moderate to Low (leveraging open formats) |
| Processing Speed | Slower for complex ad-hoc analytics | Extremely fast for SQL analytics | Fast, combining lake flexibility with warehouse speed |
| ACID Transactions | Historically poor, improving with open table formats | Robust support | Strong support (via Delta Lake, Iceberg, Hudi) |
| Primary Use Case | Raw data staging, machine learning, archiving | Business intelligence, financial reporting, BI dashboards | Unified analytics, machine learning, and enterprise reporting |
Common Challenges and Pitfalls
Managing a sprawling data universe presents significant organizational and technical hurdles. Recognizing these challenges helps prevent costly missteps.
Data Silos
As different business units adopt their own software tools and cloud environments, data silos naturally form. Marketing, sales, and engineering may maintain disconnected repositories of customer information, leading to conflicting metrics, duplicated collection efforts, and fragmented customer profiles. Eliminating silos requires centralized data modeling and cross-functional data governance committees.
Technical Debt in Pipelines
Hasty engineering practices often result in brittle ETL pipelines. When source systems change without notice, poorly documented transformation scripts break. This technical debt accumulates, consuming valuable engineering hours on firefighting rather than strategic innovation. Adopting software engineering best practices—such as version control, automated testing, and CI/CD for data pipelines—mitigates this risk.
Cost Overruns in Cloud Environments
Cloud data platforms offer near-infinite scalability, but this flexibility can lead to runaway cloud bills. Inefficient queries, unoptimized storage tiers, and forgotten idle clusters can rapidly drain budgets. Implementing FinOps (Financial Operations) practices, setting strict query budget limits, and establishing automated archiving policies are essential for cost control.
Frequently Asked Questions
What is the difference between a data lake and a data warehouse?
A data lake stores raw, unprocessed data in its native format at a low cost, making it ideal for machine learning and exploratory analysis. A data warehouse stores structured, highly cleaned data optimized for fast SQL queries and business intelligence reporting.
How does data lineage improve compliance?
Data lineage maps the exact journey of information from its source through every transformation and destination. This visibility allows organizations to rapidly locate personal identifiable information (PII) to fulfill regulatory requests such as GDPR deletion mandates.
What role does dbt (data build tool) play in the modern data stack?
dbt is a transformation workflow tool that allows analytics engineers to write modular SQL queries and transform data inside the warehouse. It introduces software engineering principles—like version control, testing, and documentation—to data transformation.
How can organizations prevent data quality issues?
Organizations can prevent data quality issues by implementing automated data observability tools, establishing clear schema contracts between upstream and downstream systems, and running automated data tests on core transformation pipelines before publishing reports.
What is FinOps in the context of data management?
FinOps is an operational framework that brings financial accountability to cloud data spending. It aligns engineering, finance, and business teams to optimize cloud infrastructure costs without sacrificing performance or scalability.
Strategic Next Actions
To successfully harness the data universe, organizations should begin with a thorough audit of their existing data assets, pipelines, and storage costs. Identify critical data silos and prioritize integration projects that directly support core business objectives. Establish a cross-functional data governance team to define ownership, enforce security standards, and improve data quality. Finally, invest in continuous training to empower teams across the enterprise to make data-driven decisions securely and efficiently.