Claude Opus 4 represents a major milestone in advanced artificial intelligence, offering sophisticated reasoning, deep contextual comprehension, and specialized technical execution for enterprise workflows. Designed to tackle complex, multi-step analytical challenges, this model builds upon previous generations by refining instruction following, reducing hallucinations, and expanding functional capabilities across coding, data analysis, and long-form content generation.
As artificial intelligence models evolve, understanding specific version iterations requires looking past marketing claims to examine core architectural shifts, practical benchmarks, integration requirements, and real-world operational limitations. Whether evaluating the model for enterprise deployment or complex research tasks, administrators must carefully balance performance advantages against infrastructure costs, token management protocols, and latency considerations.
Understanding the Claude Ecosystem and Versioning
The naming conventions within large language model ecosystems often obscure structural modifications. When evaluating advanced models, technical leads must distinguish between incremental parameter updates and fundamental changes to training methodologies, context windows, and safety alignment frameworks.
The Evolution of the Claude Architecture
Anthropic’s iterative development approach focuses on balancing raw capability with Constitutional AI safety guardrails. While earlier iterations established baseline fluency and safety filtering, subsequent generations emphasize autonomous problem-solving, precise tool use, and reduced error rates in code generation.
Understanding where an iteration sits within the broader ecosystem requires analyzing its core design goals:
- Enhanced Reasoning Depth: Moving beyond pattern matching to execute logical deductions across multi-disciplinary domains.
- Extended Context Reliability: Maintaining coherent comprehension across massive inputs without suffering from attention degradation in the middle of documents.
- Agentic Capability: Improving the model's capacity to interface with external APIs, execute code environments, and perform multi-step workflows with minimal human intervention.
Clarifying Market Nomenclature
Discussions surrounding upcoming or speculative model numbers often blend verified technical documentation with community speculation. When assessing capabilities, organizations must rely strictly on verifiable API documentation, system cards, and empirical benchmarking rather than anecdotal reports.
Core Capabilities and Technical Specifications
Advanced reasoning models derive their utility from a combination of expansive context windows, robust training datasets, and fine-tuned alignment protocols. For technical teams, evaluating a model requires a granular look at how these elements interact under production workloads.
Context Window and Information Retrieval
A defining characteristic of high-tier language models is their ability to ingest and process extensive documentation simultaneously. Rather than relying solely on external retrieval-augmented generation (RAG) pipelines for every query, models with large context windows can analyze entire codebases, legal libraries, or financial records in a single session.
However, handling large contexts introduces computational overhead and token expenditure. Developers must optimize how prompts are structured to ensure the model focuses on relevant data segments without wasting context budget on redundant preamble.
Coding, Mathematics, and Logic Benchmarks
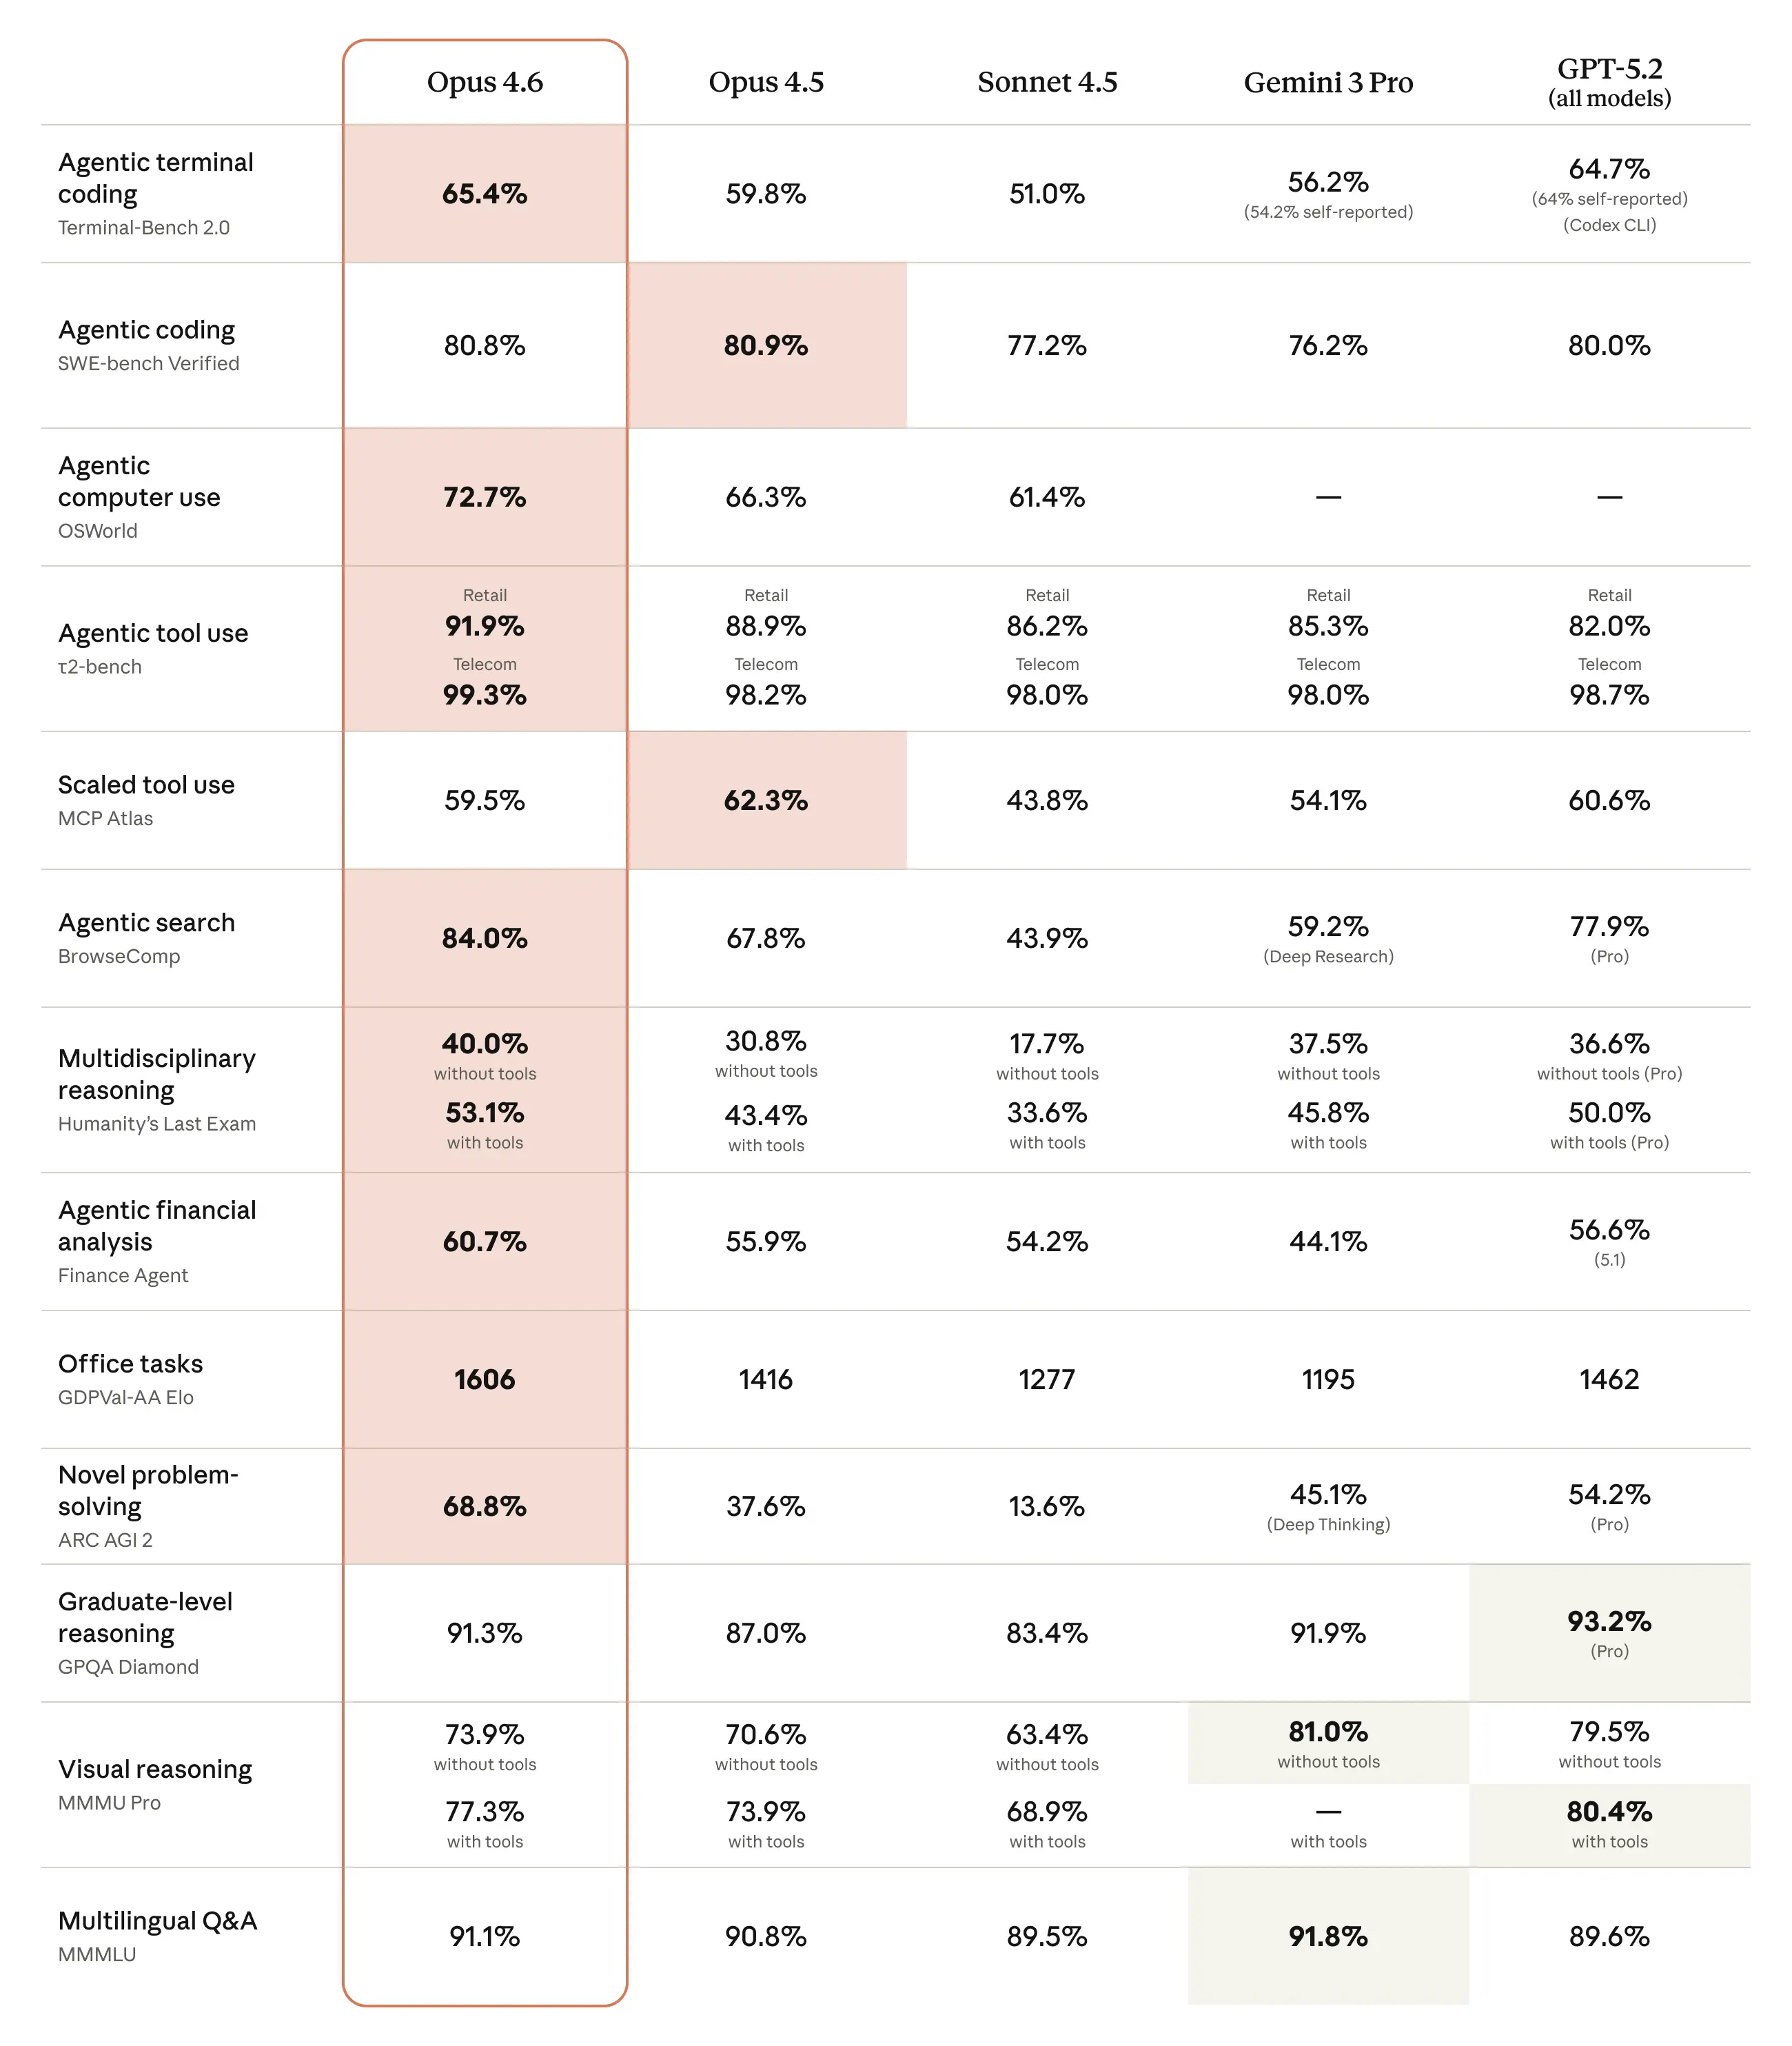
Performance across standardized benchmarks provides a baseline for comparing model capability against peers. High-tier reasoning engines typically excel in:
- Software Engineering: Writing, debugging, and refactoring complex codebases across multiple programming languages.
- Formal Logic: Solving multi-variable constraint problems and abstract reasoning puzzles.
- Data Synthesis: Extracting actionable insights from unstructured text and transforming them into structured formats like JSON or Markdown tables.
| Evaluation Metric | Typical Baseline Model | Advanced Reasoning Model (e.g., Opus Class) |
|---|---|---|
| Context Window Capacity | Standard (e.g., 32k - 128k tokens) | Extended (100k+ tokens with high recall) |
| Multi-Step Coding Tasks | Moderate success; requires frequent handholding | High autonomy; handles multi-file refactoring |
| Instruction Adherence | Prone to drift on complex, nested constraints | Strict adherence to multi-layered system prompts |
| Latency Profile | Low latency; optimized for rapid chat | Higher time-to-first-token due to deep reasoning |
Operational Requirements and Integration Workflows
Deploying a high-capability language model into a production environment involves navigating architectural prerequisites, rate limits, API integration patterns, and security compliance standards.
API Integration and SDK Utilization
Interfacing with modern AI infrastructure requires robust error handling, asynchronous request management, and efficient token streaming. Developers typically interact with these models via official software development kits (SDKs) or direct REST endpoints.
- Authentication and Security: Provisioning secure API keys, managing environment variables, and enforcing least-privilege access control within cloud infrastructure.
- Payload Optimization: Structuring system instructions to define persona, behavioral constraints, and output formats clearly.
- Stream Management: Implementing Server-Sent Events (SSE) to handle token streaming for real-time user interfaces, reducing perceived latency.
Token Management and Cost Control
Advanced reasoning models consume significantly more compute resources per inference than lightweight classification models. Organizations must implement strict monitoring to prevent unexpected budget overruns:
- Set hard limits on daily API expenditures at the organizational level.
- Implement client-side token counting libraries to estimate payload sizes before dispatching requests.
- Utilize caching mechanisms for static system prompts and reference documentation to reduce redundant processing costs.
Comparative Analysis: Strengths and Operational Limitations
Every AI model involves trade-offs. While raw intelligence and reasoning depth increase with advanced architectures, operational costs, inference latency, and edge-case failure modes also shift.
Primary Advantages
- Reduced Prompt Engineering Overhead: Complex instructions that previously required multi-shot examples can often be executed accurately with clear, concise zero-shot prompts.
- Superior Synthesis: Excellent ability to bridge disparate concepts from different fields, making it valuable for research and technical writing.
- Nuanced Tone Control: Capable of adopting specific stylistic guidelines and maintaining consistent voice across extended outputs.
Notable Limitations and Edge Cases
- Inference Latency: Deep reasoning processes inherently require more compute time, resulting in slower response times compared to smaller, faster models.
- Hallucination under Uncertainty: When faced with obscure or missing information, sophisticated models can occasionally generate plausible-sounding fabrications rather than explicitly stating ignorance.
- Cost Prohibitiveness: Running high-volume production workflows entirely on top-tier frontier models is financially inefficient for simple classification or extraction tasks.
Best Practices for Enterprise Implementation
To maximize the value of advanced language models while mitigating risks, organizations should adhere to structured deployment methodologies.
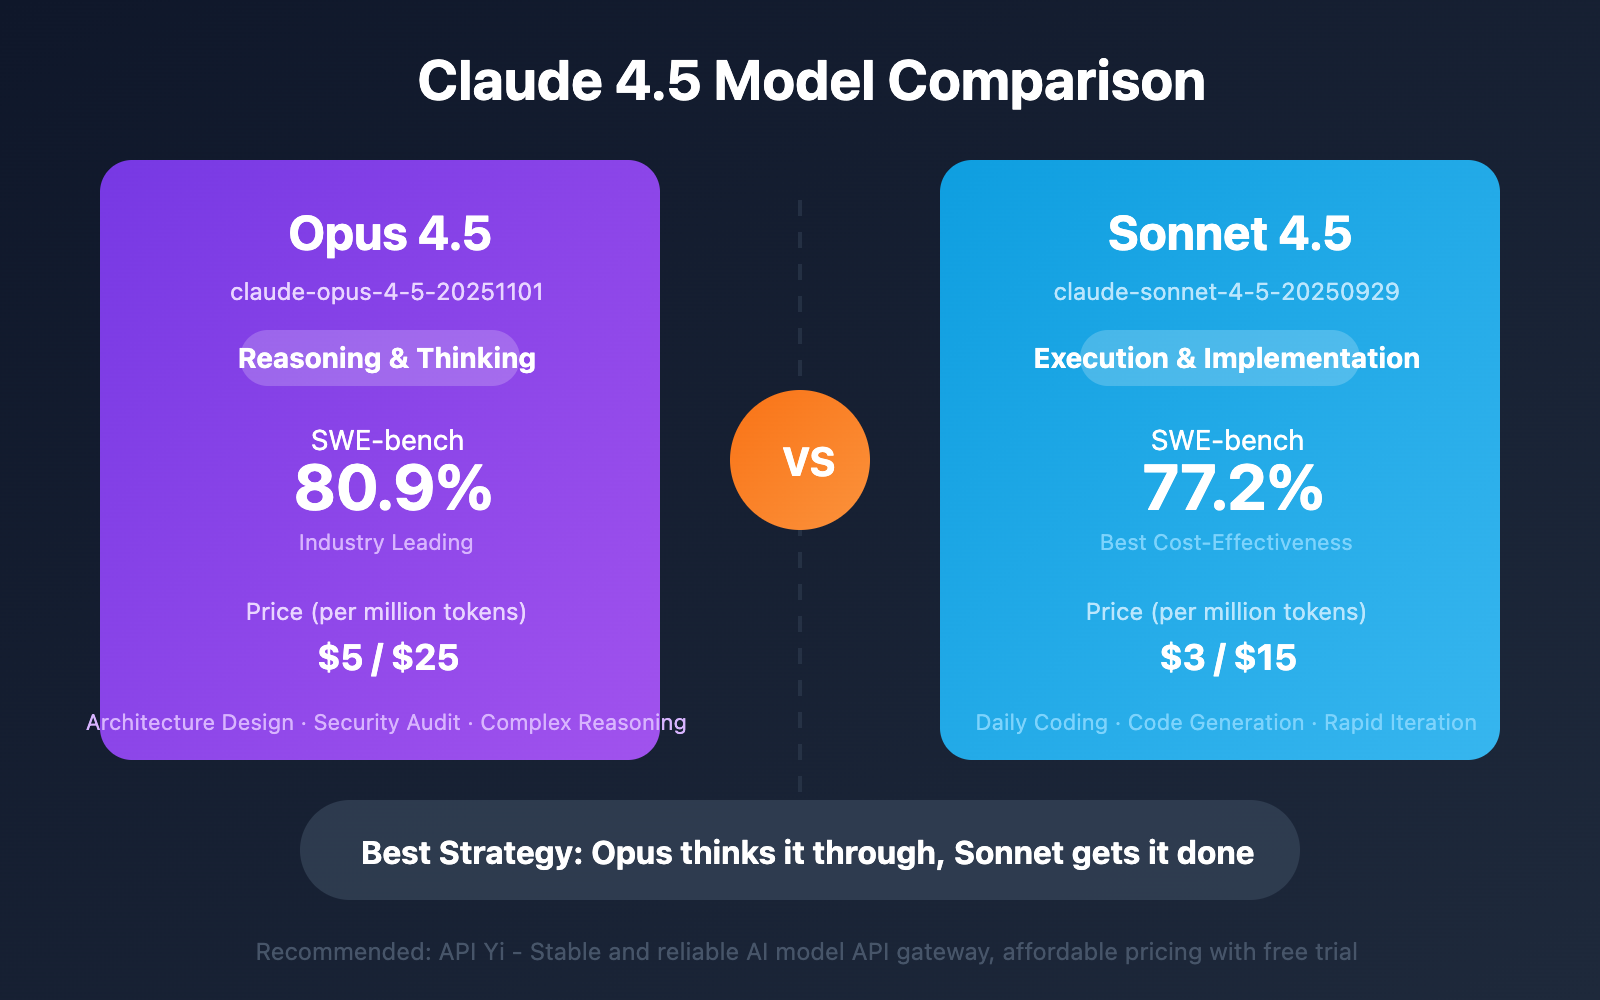
- Task Routing: Implement a tiered routing architecture. Direct simple classification, summarization, and routing tasks to fast, lightweight models; reserve advanced reasoning engines for complex coding, deep analysis, and multi-step problem solving.
- Human-in-the-Loop Validation: For high-stakes domains such as legal compliance, financial advisory, and automated code deployment, always require human review before executing model-generated outputs.
- Rigorous Prompt Versioning: Treat system prompts and context templates as code. Store them in version-controlled repositories, run regression tests against benchmark queries, and track performance changes across model updates.
Frequently Asked Questions
What distinguishes top-tier reasoning models from standard chat models?
Top-tier reasoning models are trained to allocate more internal compute toward logical deduction, constraint satisfaction, and multi-step planning before generating a response. This reduces logical errors in coding and complex analysis compared to general-purpose chat models optimized primarily for conversational fluency.
How does context window size impact API costs?
API pricing scales with the total number of input and output tokens processed. Ingesting large documents into the context window for every request increases costs significantly. Utilizing prompt caching features—where available—mitigates this by storing frequently accessed context on the server side.
Can advanced models replace software developers entirely?
No. While advanced models excel at writing boilerplate code, refactoring existing functions, and debugging syntax errors, they lack business context, architectural foresight, and accountability. They function best as force multipliers for human engineers rather than autonomous replacements.
What are the primary security risks when deploying large language models?
Key risks include prompt injection attacks (where malicious inputs trick the model into bypassing safety filters), data leakage (inadventently sending sensitive proprietary data to third-party APIs), and hallucinations leading to unverified code execution in production environments.
How can organizations reduce model latency in production?
Organizations can reduce latency by utilizing streaming responses, optimizing prompt length to remove redundant instructions, deploying models within geographically proximate cloud regions, and caching static reference data.
Conclusion and Next Actions
Deploying advanced artificial intelligence models like Claude Opus 4 requires a balanced strategy that weighs exceptional reasoning capabilities against operational costs and latency constraints. Organizations should begin by auditing existing workflows to identify bottlenecks where deep reasoning provides tangible return on investment. Next, establish a controlled sandbox environment to benchmark model performance against proprietary datasets, ensuring output accuracy, security compliance, and cost predictability before launching customer-facing integrations.