An index search is a specialized retrieval process that queries pre-compiled data structures rather than scanning raw datasets sequentially. By leveraging sorted lists, hash tables, and inverted indices, it drastically reduces query latency, enabling sub-millisecond information retrieval across enterprise databases, local operating systems, and global web search engines.
Understanding the Fundamentals of Index Search
To understand how an index search operates, one must first distinguish it from a full-table or linear scan. In a linear scan, a system inspects every single record or document from start to finish until it finds matches. While straightforward, this method scales linearly with dataset size ($O(N)$ time complexity), making it computationally prohibitive for millions or billions of items. An index search bypasses this bottleneck by consulting a pre-built reference map—the index—which points directly to the physical storage location of the target data.
The core principle mirrors the index at the back of a textbook. Instead of reading every page to find mentions of a specific concept, a reader looks up the term alphabetically and jumps straight to the relevant pages. In digital systems, this lookup relies on advanced data structures designed for high-speed traversal, transforming the time complexity of retrieval operations down to logarithmic ($O(\log N)$) or even constant ($O(1)$) time.
The Mechanics of Data Structuring
Building an index requires upfront computational effort and storage space. When new data enters a system, the indexing engine parses the content, extracts key identifiers or tokens, and organizes them into a structured hierarchy. Common underlying data structures include:
- B-Trees and B+ Trees: Self-balancing search trees that keep data sorted and allow searches, sequential access, insertions, and deletions in logarithmic time. They serve as the backbone for relational database indexes.
- Hash Indexes: Structures that use a hash function to map keys directly to specific storage buckets. They excel at exact-match lookups but struggle with range queries.
- Inverted Indexes: Essential for text search engines, these map terms (words) to their exact locations within a set of documents, allowing rapid lookup of keywords across large text corpora.
Types of Index Searches Across Domains
Index search is not a monolithic technology; its implementation varies depending on the target environment, the nature of the data, and the primary search intent. Evaluating these variations helps developers and administrators select the right tool for specific workloads.
Database Index Searches
In structured database management systems (DBMS), an index search is triggered automatically by the query optimizer when a WHERE clause references an indexed column.
- Clustered Indexes: The database sorts and stores the data rows in the table based on the indexed key. Because the physical rows are ordered, a table can have only one clustered index.
- Non-Clustered Indexes: The index structure is separate from the data rows. It contains the key values and pointers (locators) directing the database engine to the actual data row. Multiple non-clustered indexes can exist on a single table.
Enterprise and Full-Text Search
Unstructured and semi-structured data—such as emails, PDF documents, and web pages—require full-text search capabilities powered by engines like Apache Lucene, Elasticsearch, or OpenSearch.
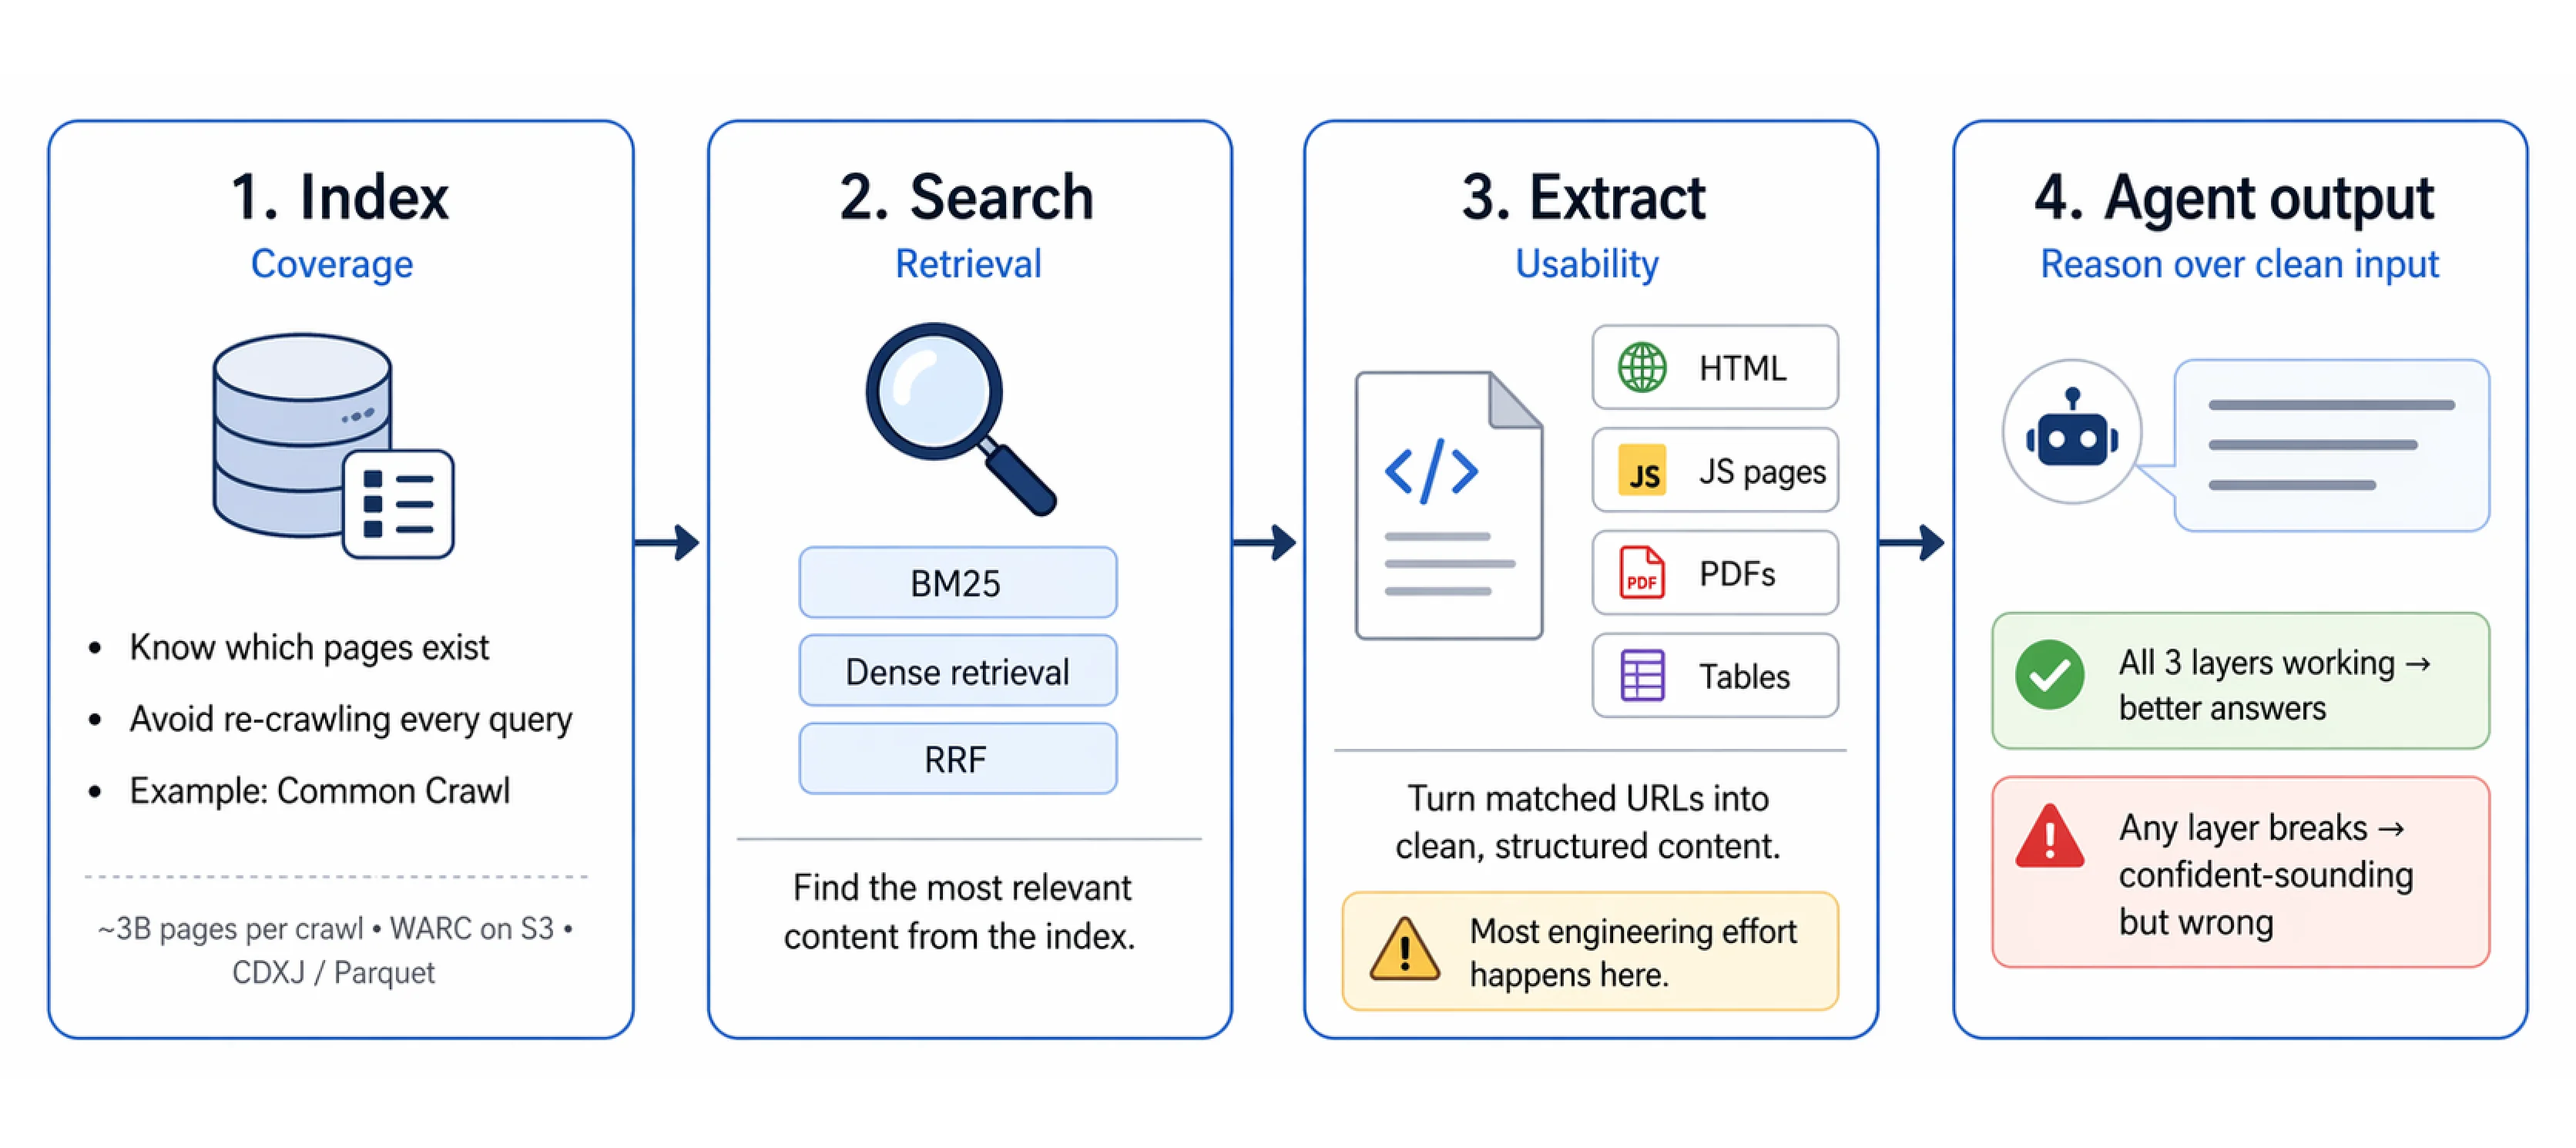
An enterprise index search parses human language through tokenization, stemming (reducing words to their root forms), and stop-word removal (stripping out common words like "and" or "the"). When a user executes a query, the engine matches terms against the inverted index, calculates relevance scores using algorithms like BM25, and returns the most pertinent results sorted by rank.
Web Search Engine Indexing
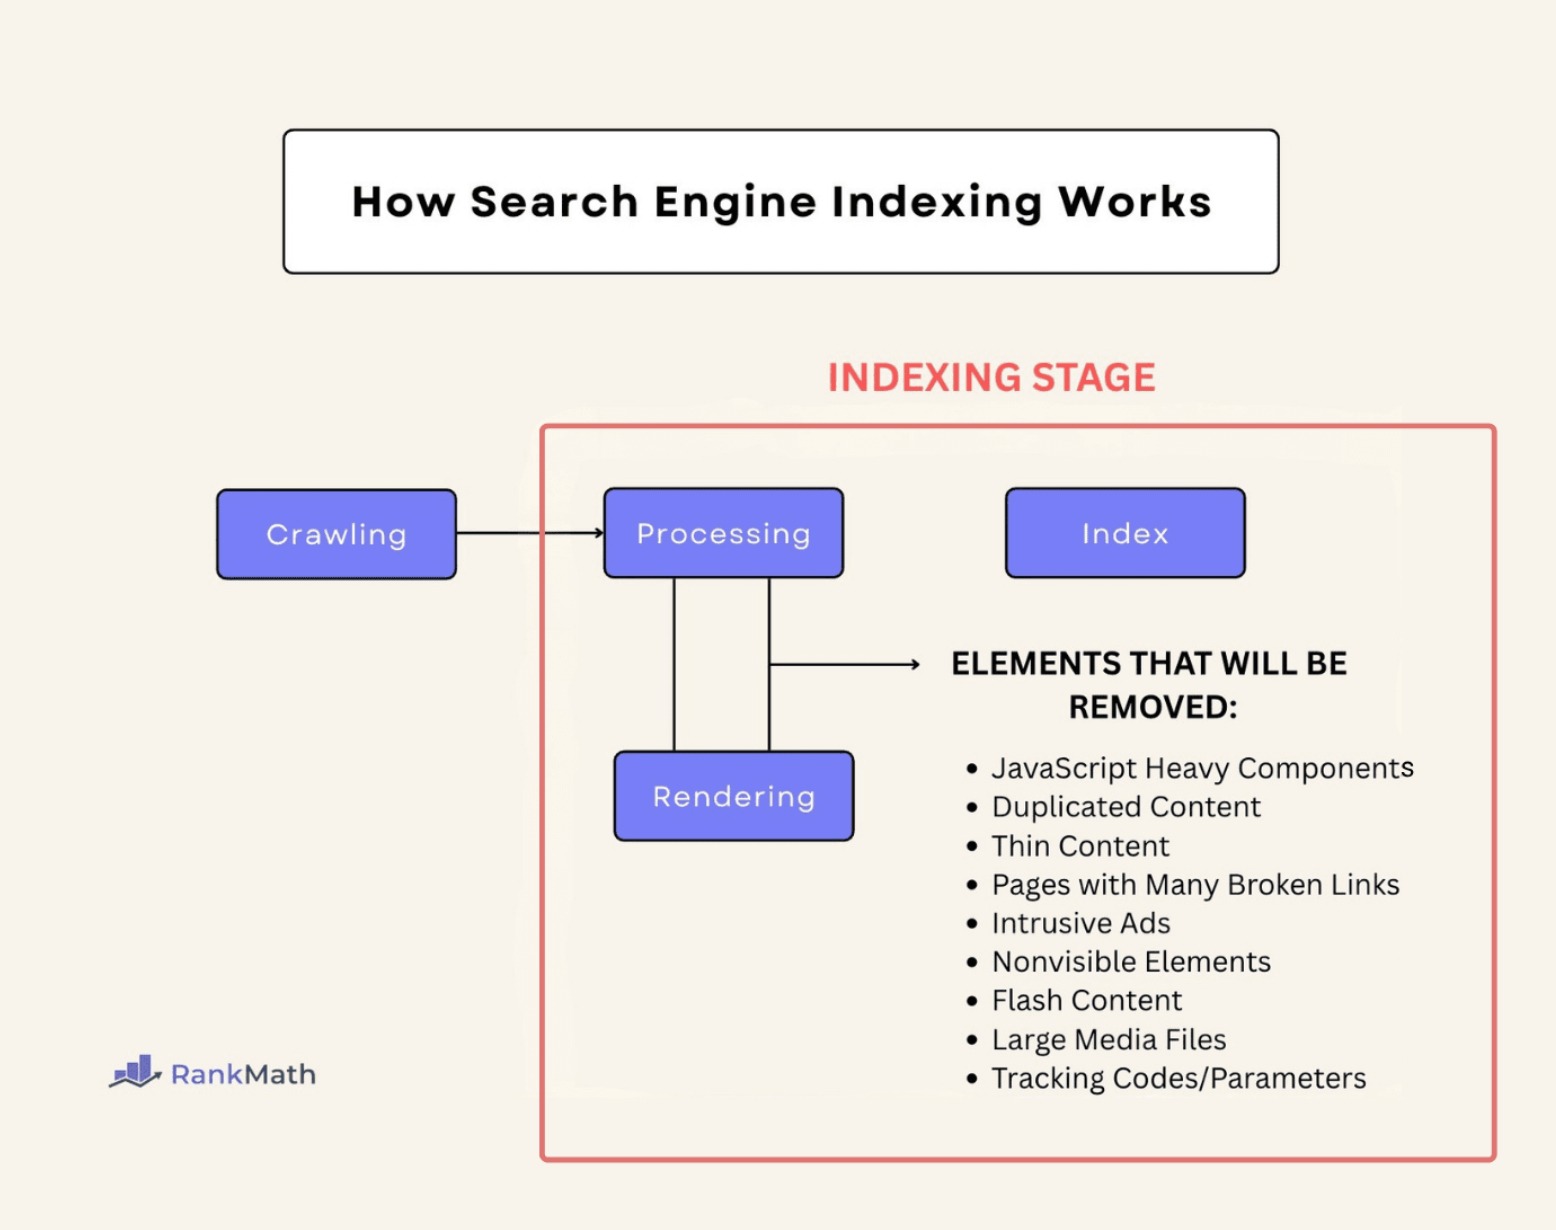
Web search engines operate on a planetary scale. Software crawlers discover web pages, download their content, and feed them into massive distributed indexing pipelines. When an end user types a query into a search bar, the engine executes an index search across an immutable, compressed inverted index distributed across thousands of server nodes, returning results in milliseconds.
Comparison of Index Search Mechanisms
Different indexing strategies serve distinct architectural requirements. The table below compares the primary index search mechanisms across key performance and structural metrics.
| Index Type | Primary Data Structure | Time Complexity (Lookup) | Best Use Case | Key Limitation |
|---|---|---|---|---|
| B-Tree Index | Balanced Tree | $O(\log N)$ | Relational databases, range queries | Requires maintenance overhead on write operations |
| Hash Index | Hash Table | $O(1)$ | Exact-match lookups, key-value stores | Inefficient for range scans or sorting |
| Inverted Index | Term-to-Document Map | $O(K)$ (where $K$ is term frequency) | Full-text search, document retrieval | High storage overhead for large vocabularies |
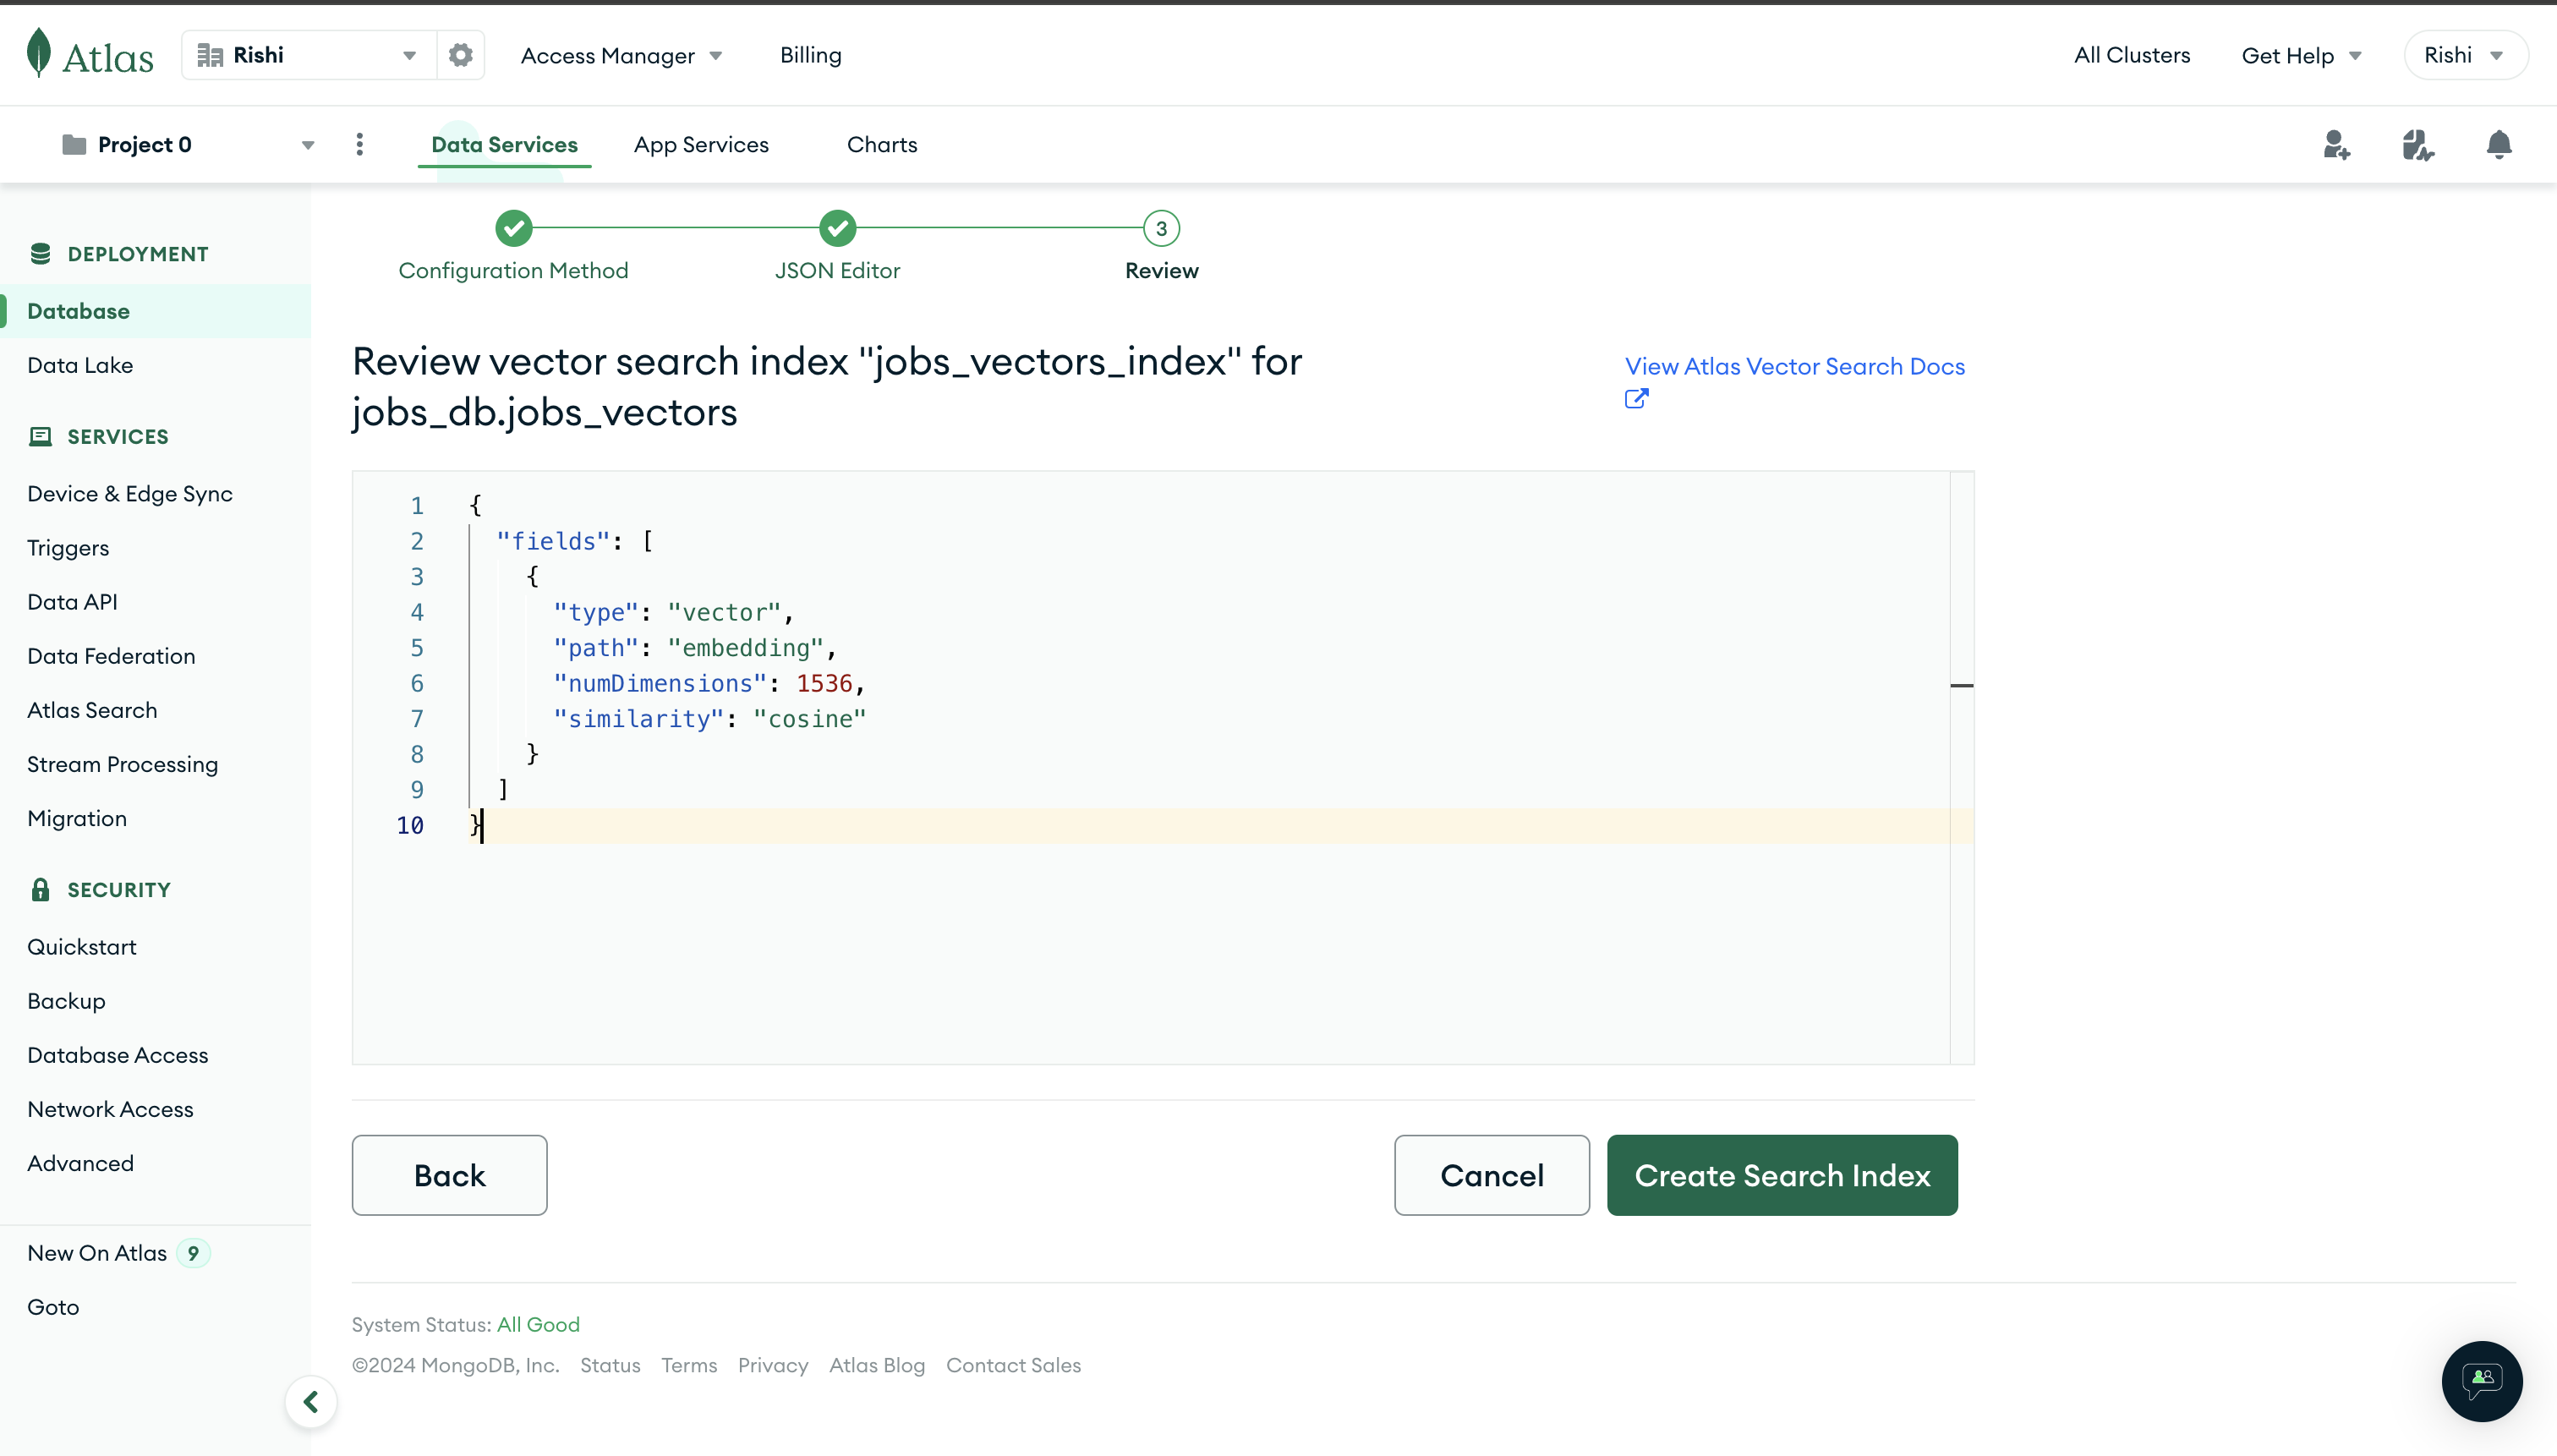
| Vector Index | Graph/Quantized Space | $O(\log N)$ to $O(N)$ | Semantic search, AI embeddings, similarity matching | Approximate results rather than exact matches |
Prerequisites and Setup Requirements
Deploying an efficient index search system requires careful planning regarding hardware, schema design, and resource allocation. Neglecting these prerequisites often leads to degraded query performance and bloated storage costs.
Hardware and Resource Planning
- Memory (RAM): For optimal performance, index structures—particularly hot segments in full-text search engines and database buffer pools—should fit entirely within RAM. Disk-based lookups introduce significant latency.
- Storage I/O: Solid-state drives (SSDs) or NVMe drives are mandatory for modern indexing systems to handle random read operations during deep pagination or segment merging.
- CPU Allocation: Index building, tokenization, and vector embedding calculations are CPU-intensive tasks. Multicore processors are necessary to handle concurrent query loads and background index updates.
Schema and Mapping Configuration
Before indexing data, administrators must define precise field mappings. In full-text search, choosing the correct analyzer dictates how text is sliced and searched. For instance, applying a lowercase filter and a stemming filter ensures that searches for "Running" successfully match documents containing "run". In databases, indexing every column is a common anti-pattern; indexes should be restricted to columns frequently used in WHERE clauses, JOIN conditions, and ORDER BY statements.
Optimization Strategies for Index Search
Even a well-designed index can degrade over time due to data fragmentation, shifting query patterns, or unoptimized query syntax. Maintaining high performance requires ongoing tuning and maintenance.
Managing Index Fragmentation
Over time, frequent insertions, updates, and deletions cause fragmentation in B-Trees and database indexes, leading to sequential scan inefficiencies and wasted disk space. Database administrators must schedule regular index maintenance tasks, such as rebuilding or reorganizing indexes during off-peak hours.
Query Tuning and Execution Plans
Understanding how an execution engine interprets a search query is vital. Administrators should utilize query execution plans (EXPLAIN or EXPLAIN ANALYZE commands) to verify whether the engine is performing an index scan or falling back to an expensive sequential table scan. Common causes of index bypass include:
- Applying functions or mathematical operations directly to indexed columns in the query predicate (e.g.,
WHERE YEAR(date_column) = 2026). - Using leading wildcards in text searches (e.g., searching for
*searchinstead ofsearch*). - Implicit data type conversions that prevent the engine from utilizing the index tree.
Common Mistakes and Troubleshooting
Troubleshooting an underperforming index search involves isolating bottlenecks across ingestion, storage, and query execution.
Over-Indexing
A frequent pitfall is creating an index for every column or field in anticipation of future queries. While this speeds up read operations, every write, update, or delete operation forces the system to update all associated indexes. This write amplification severely degrades ingestion throughput and inflates storage requirements.
Ignoring Update Latency
In search engines and real-time databases, there is often a trade-off between indexing latency and search visibility. If a system batches index updates to save CPU cycles, newly written data will not appear immediately in search results. Applications requiring strict read-after-write consistency must configure near-real-time (NRT) indexing parameters carefully.
Stale Statistics
Query optimizers rely on statistical data regarding the distribution of values within an index to choose the most efficient execution path. If these statistics become outdated due to rapid data churn, the optimizer may select a slow full-scan instead of a fast index search. Regularly updating database statistics resolves this issue.
Frequently Asked Questions
What is the difference between a table scan and an index search?
A table scan inspects every single row in a dataset sequentially to find matches, resulting in $O(N)$ time complexity. An index search uses a pre-built data structure—such as a B-Tree or inverted index—to locate the physical storage address of matching records directly, achieving logarithmic or constant time complexity.
Does an index search speed up all types of database queries?
No. Index searches accelerate queries involving exact matches, sorting, and specific range filters on indexed columns. They do not help with queries that scan entire tables for aggregation without filters, nor do they improve performance when querying unindexed columns.
Why do write operations become slower when many indexes are present?
Every time a record is inserted, updated, or deleted, the system must update not only the primary data table but also every associated index (clustered, non-clustered, or full-text). This additional overhead is known as write amplification.
How often should database indexes be rebuilt?
The frequency of index rebuilding depends on the rate of data churn (insertions, updates, and deletions). Systems with high transaction volumes may require scheduled weekly or monthly fragmentation checks and index reorganizations, whereas read-heavy static datasets rarely need rebuilding.
Can an index search handle fuzzy or misspelled queries?
Standard exact-match indexes cannot handle misspellings, but advanced full-text search engines and vector indexes support fuzzy matching, phonetic algorithms, and semantic similarity searches to return relevant results despite typos.
Conclusion
An index search is the foundational mechanism that transforms raw data into rapidly retrievable intelligence. By understanding the underlying data structures, selecting the appropriate indexing strategy for your specific domain, and maintaining indexes through regular tuning, you can eliminate latency bottlenecks and ensure high-performance data retrieval across applications.