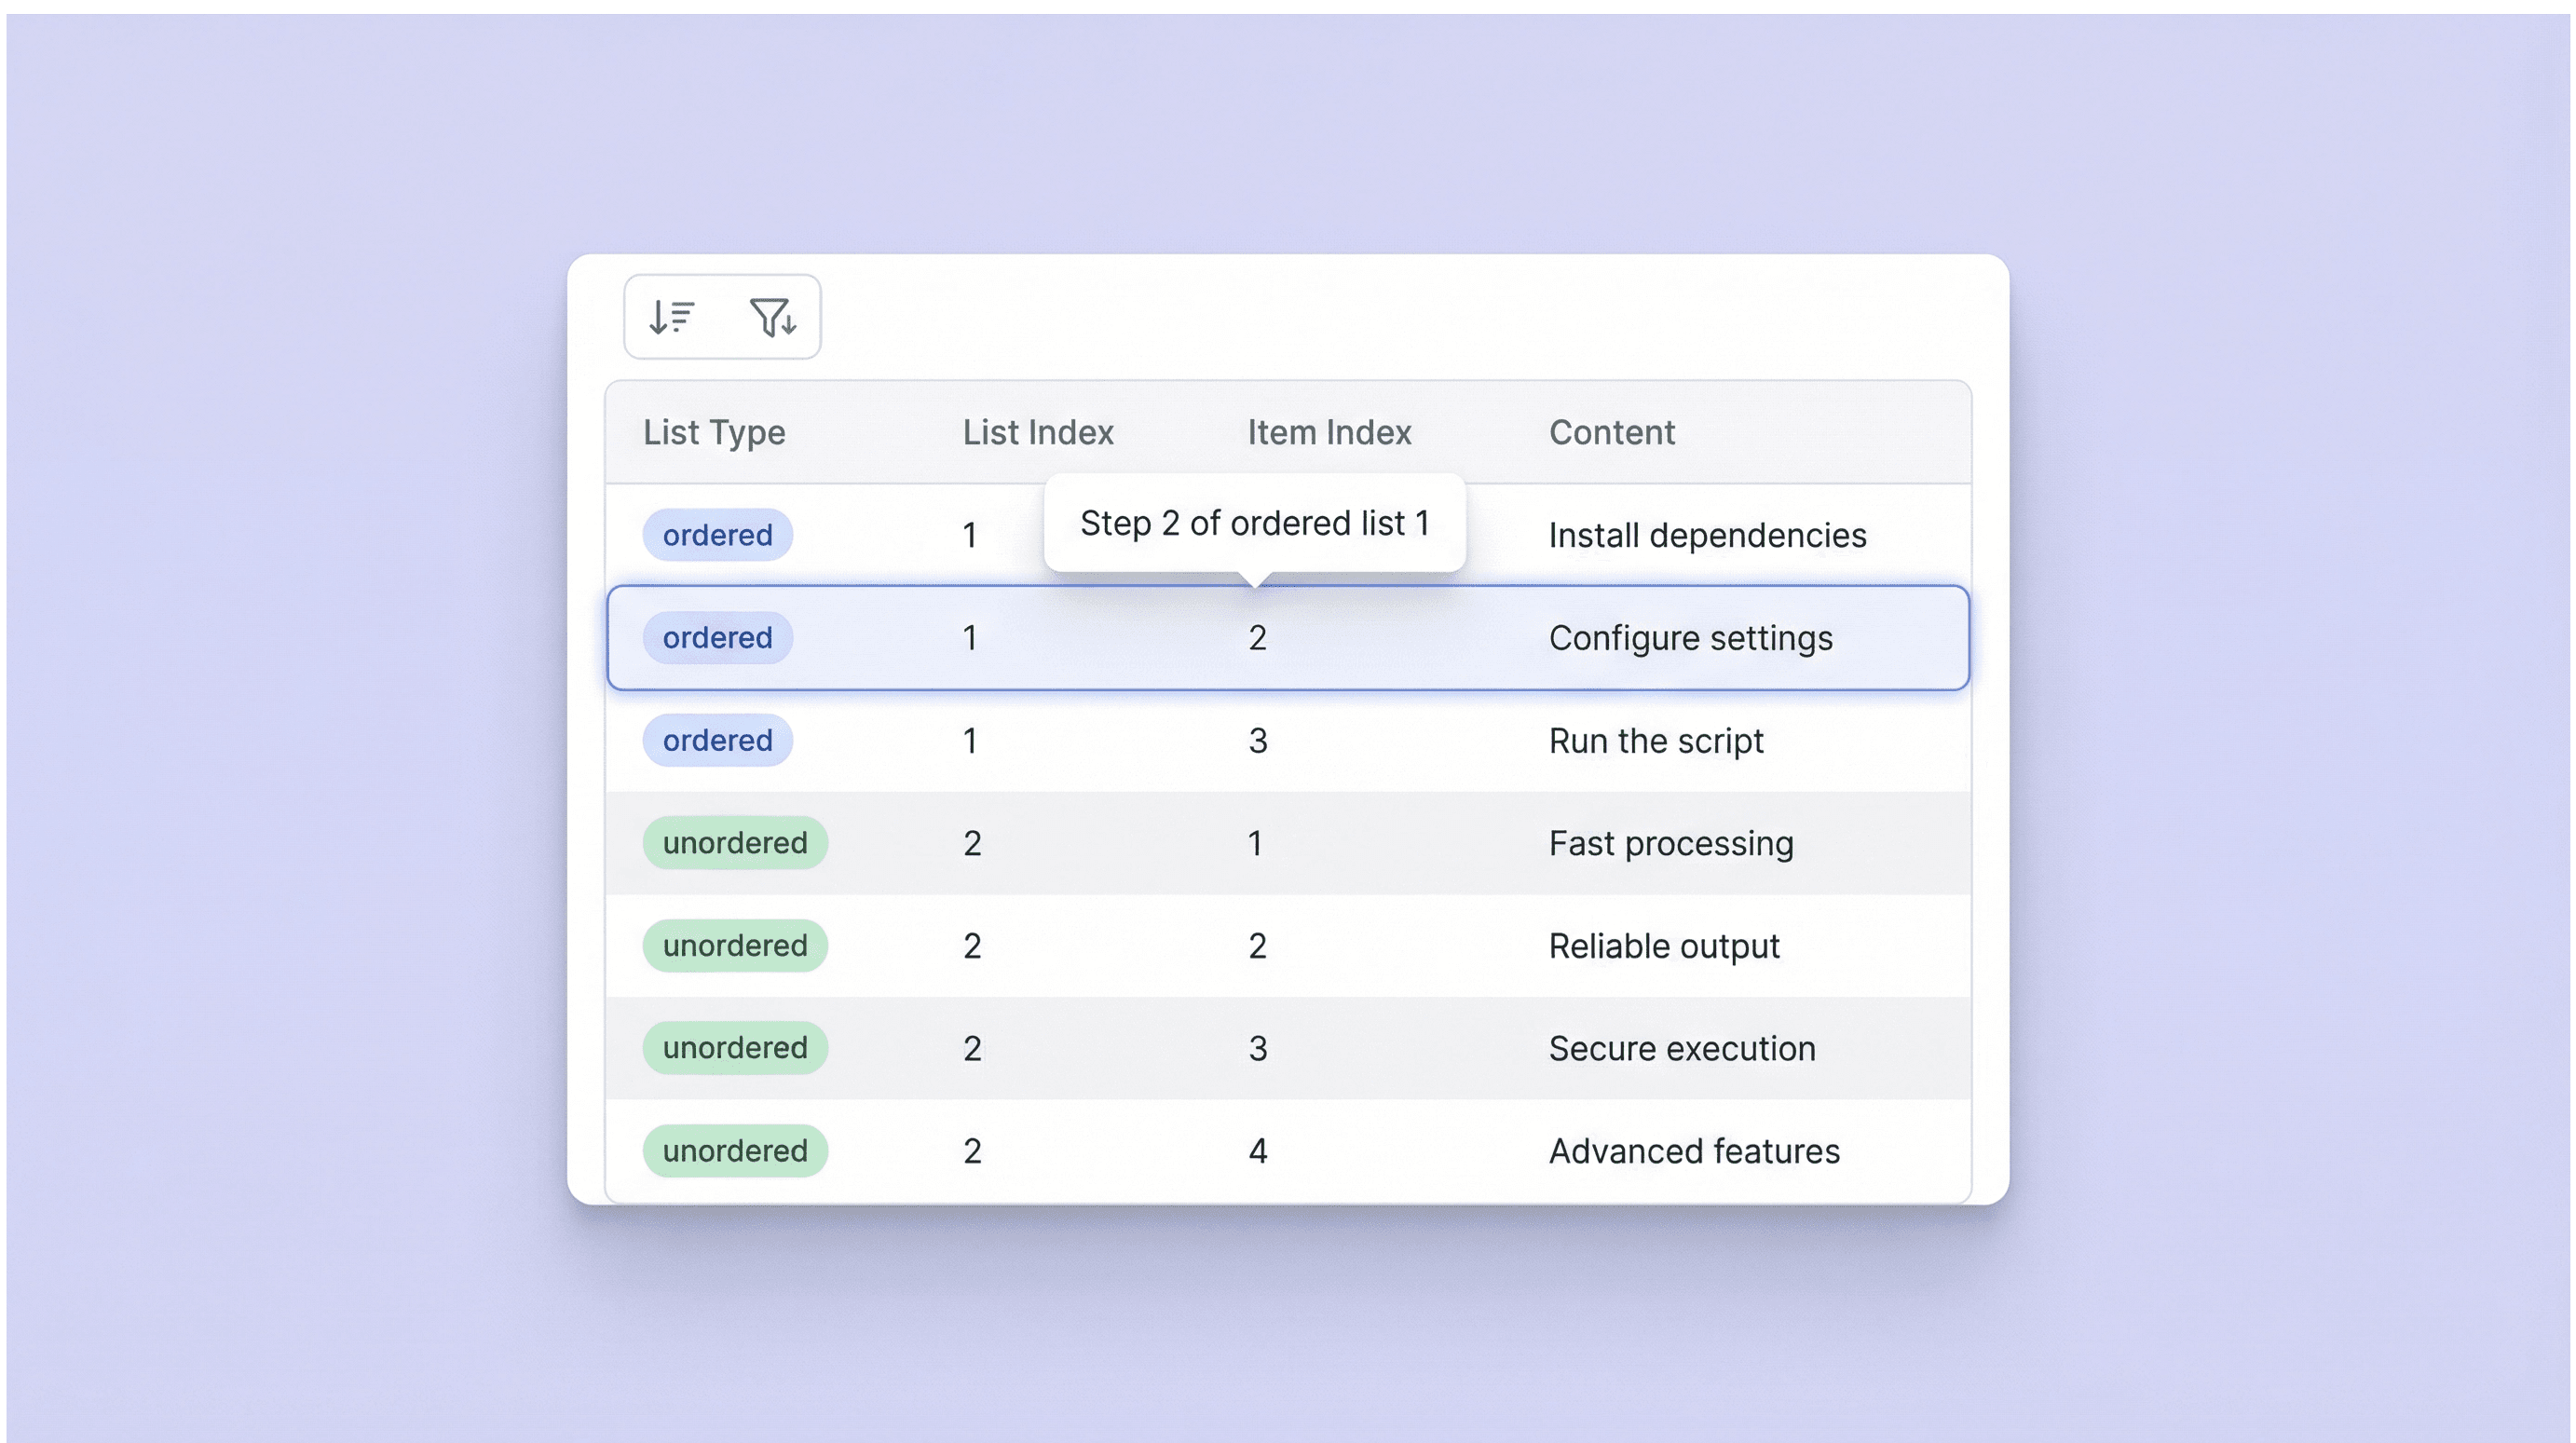
A list crawler is a specialized software agent or script designed to systematically navigate web pages to identify, extract, and compile specific data points—such as URLs, product catalogs, contact information, or directory listings—into a structured format. By automating the discovery of lists across websites, these tools enable users to aggregate large datasets efficiently without manual data entry.
The Mechanism of List Crawling
At its core, a list crawler functions as a targeted subset of a web spider. While a general-purpose search engine crawler attempts to index the entire web, a list crawler is typically configured to prioritize "index pages," "category pages," or "result lists."
The process begins with a seed URL, which serves as the entry point. The crawler fetches the HTML content of the page, parses the DOM (Document Object Model), and identifies links that match specific patterns—often CSS selectors or XPath expressions corresponding to list items. Once identified, the crawler follows these links to extract deeper information or iterates through pagination parameters to uncover the full extent of the list.
Distinguishing Between Crawlers and Scrapers
While the terms are often used interchangeably, there is a technical distinction. A crawler is primarily responsible for discovery and navigation—it finds where the data lives. A scraper is responsible for the actual extraction and parsing of the data within those pages. A "list crawler" usually implies a combined utility that navigates a pagination sequence (crawling) and pulls the relevant entries from each page (scraping).
Prerequisites and Technical Requirements
To implement a list crawler, you must establish a clear technical foundation. Attempting to crawl sites without proper preparation often results in IP blocks or corrupted data.
- Defining Scope: Determine the exact structure of the target list. Are the items contained within
or tags? Are they loaded dynamically via JavaScript?- Environment Setup: You will need a runtime environment, such as Python with libraries like
BeautifulSouporScrapy, or a headless browser likePlaywrightorSeleniumif the list requires interaction (e.g., clicking "Load More" buttons). - Proxy Management: Frequent requests to a single domain can trigger rate limiting or CAPTCHAs. Residential or data-center proxies are often necessary to distribute requests across multiple IP addresses.
- Robots.txt Adherence: Always check the
robots.txtfile of the target domain to ensure your crawling behavior complies with the site owner’s specified crawling policies.
Comparison of Crawling Methods
| Method | Best For | Technical Complexity | Performance |
|---|---|---|---|
| Static Parsing | HTML-based lists | Low | High |
| Headless Browsers | JavaScript-heavy sites | High | Low |
| API Integration | Structured internal data | Medium | Very High |
| Regex Extraction | Unstructured text patterns | Medium | Moderate |
Operational Workflow for List Extraction
When setting up a list crawler, follow a structured sequence to ensure data integrity and system stability.
1. Discovery and Pagination Handling
The most common challenge in list crawling is pagination. Most lists are split across multiple pages. Your crawler must identify the "Next" button URL or the numeric sequence in the query string (e.g., ?page=1, ?page=2). If the pagination uses infinite scroll, your crawler must be capable of scrolling to the bottom of the page to trigger new content loads.
2. Parsing Logic
Once the list items are identified, define the specific elements to capture. For a directory list, this might include the name, address, phone number, and a link to the profile page. Using reliable CSS selectors or XPath is critical here. If the layout of the website changes, your crawler will need updated selectors to remain functional.
3. Data Cleaning and Normalization
Raw data extracted from a website is rarely ready for use. It often contains trailing whitespace, HTML entity encoding (like &), or inconsistent formatting. Incorporate a normalization layer in your script to cast data types, handle missing values, and standardize date or currency formats before outputting to CSV, JSON, or a database.
Common Pitfalls and Troubleshooting
Even well-designed crawlers encounter frequent hurdles. Understanding these is essential for maintaining a production-ready system.
- IP Blocking: If you receive
403 Forbiddenor429 Too Many Requestserrors, your request rate is likely too high. Implement request throttling or delay intervals between calls. - Dynamic Content: If your logs show empty lists despite correct CSS selectors, the content is likely generated by client-side JavaScript. Switch to a browser automation tool that executes JavaScript.
- Data Degradation: Website owners update designs frequently. A crawler that worked perfectly yesterday may fail today due to a change in class names or ID structures. Implementing robust error logging and "health check" notifications is standard practice in 2026 for automated data pipelines.
- Authentication Requirements: Some lists are behind login walls. If you must log in, ensure your crawler maintains a session cookie and handles CSRF tokens correctly.
Ethical and Legal Considerations
Automated list crawling must be performed with respect for the host's resources and legal boundaries. Avoid aggressive crawling that impacts the server's availability (DDoS-like behavior). Furthermore, ensure you are not violating Terms of Service (ToS) that explicitly prohibit automated data collection.
Be aware of data protection regulations such as GDPR or CCPA. If the lists you are crawling contain personal information, you are responsible for how that data is stored, processed, and potentially shared. Always prioritize public, non-sensitive data and consult legal counsel if your project involves proprietary or sensitive information.
Frequently Asked Questions
Can a list crawler handle infinite scroll pages? Yes, but it requires specialized tools. A static crawler will only see the initial items loaded in the HTML. You must use a browser automation framework like Playwright or Selenium to programmatically scroll the viewport, allowing the JavaScript to inject subsequent list items into the DOM before extraction.
How often should I update my crawl? The frequency depends entirely on the volatility of the source data. If you are tracking a product price list that updates hourly, you will need high-frequency polling. For a static directory that changes monthly, a once-a-week crawl is sufficient and reduces the load on the host server.
What is the best language for building a list crawler? Python is the industry standard due to its comprehensive ecosystem of libraries like Scrapy, Playwright, and BeautifulSoup. These tools are well-documented, highly supported by the community, and efficient for handling both small-scale and enterprise-level crawling tasks.
Is it legal to crawl public lists?
Generally, accessing publicly available data is permitted, but it occupies a legal grey area depending on the jurisdiction and the specific site's ToS. Always respect robots.txt and ensure your activities do not cause technical harm to the target website.
How do I handle CAPTCHAs during crawling? If you encounter CAPTCHAs, it is usually a sign that your crawling behavior mimics a bot too closely. Before resorting to third-party CAPTCHA-solving services, try rotating your User-Agent strings, using reputable proxy providers, and introducing human-like delays into your request intervals.
Recommendations for Success
If you are planning to deploy a list crawler, start by building a small-scale proof of concept using a single site with a predictable structure. Focus on building a resilient "extraction engine" that can handle common errors such as connection timeouts or unexpected null values in the data. Once the core logic is stable, introduce features like proxy rotation and scheduled cron jobs. For large-scale operations, consider moving your infrastructure to cloud-based containers, which allow you to scale resources up or down based on the size of the lists being processed.