Integrating optical character recognition into mobile software allows developers to transform raw images, camera feeds, and documents into searchable, machine-readable text directly on Apple mobile devices. By deploying a specialized software development kit, engineering teams can build high-performance scanning features without engineering text recognition algorithms from scratch.
Modern applications require instantaneous text extraction for workflows ranging from passport scanning and receipt processing to augmented reality translation and automated data entry. Choosing and implementing the right text recognition development kit on Apple's mobile operating system involves evaluating native frameworks against third-party enterprise tools, managing hardware constraints, optimizing memory usage, and addressing strict user privacy requirements.
Understanding Optical Character Recognition on Apple Mobile Operating Systems
Optical character recognition technology bridges the gap between unstructured visual data and structured digital information. On Apple's mobile platform, this capability relies heavily on hardware acceleration, specialized neural processing units, and sophisticated computer vision algorithms. Developers can choose between Apple's native Vision framework and third-party commercial options.
Native Frameworks Versus Commercial SDKs
Apple provides a robust, built-in solution via the Vision framework paired with the Core ML infrastructure. These native tools are optimized specifically for Apple's custom silicon, ensuring deep integration with iOS hardware without introducing external binary weight or licensing fees. Native APIs handle standard text recognition tasks efficiently across supported devices.
However, commercial alternatives developed by specialized vendors often offer advanced features tailored for specific verticals. These proprietary kits may include pre-trained models for specialized documents such as identity cards, driver licenses, international passports, vehicle identification numbers, and complex financial invoices. When evaluating these options, development teams must weigh licensing costs against the engineering hours required to build custom parsers on top of a native foundation.
Core Architecture and Processing Pipeline
A standard text recognition pipeline consists of several distinct stages running sequentially or concurrently:
- Image Acquisition: Capturing frames from the device camera or loading static image files from storage.
- Preprocessing: Enhancing image quality by adjusting contrast, correcting perspective distortion, cropping borders, and reducing noise.
- Text Localization: Identifying the spatial bounding boxes where text blocks, lines, or individual characters reside within the frame.
- Character Recognition: Analyzing the localized pixel patterns to map visual shapes to corresponding text characters using neural networks.
- Post-Processing: Applying linguistic dictionaries, regular expressions, and context-aware correction models to fix common recognition errors.
Evaluating Technical Requirements and Prerequisites
Successful integration of a text recognition kit requires careful planning regarding device compatibility, development environment setup, and performance benchmarks.
Hardware and OS Compatibility
Apple's mobile software ecosystem evolves rapidly, and modern machine learning frameworks often leverage advanced hardware instructions available only on newer chipsets. While basic text recognition can run on older devices, high-speed, real-time video text extraction generally requires neural engine capabilities found in Apple A12 Bionic chips and newer. Development teams must define their minimum supported device target early to ensure the chosen SDK performs adequately across their entire user base.
Development Environment Setup
Integrating an external library typically involves package management tools such as the Swift Package Manager or CocoaPods. Developers must configure proper project permissions, specifically requesting camera access usage descriptions within the Info.plist file. Furthermore, configuring compilation flags for architecture slices (such as arm64 for physical devices versus x86_64 for the iOS Simulator) prevents common build-time failures.
Key Features to Demand in an Enterprise-Grade Text Recognition Tool
Selecting the correct toolkit requires an objective assessment of features that impact end-user experience and developer productivity.
| Feature Category | Native Vision Framework | Enterprise Third-Party SDK |
|---|---|---|
| Licensing & Cost | Free, included with iOS | Commercial licensing fees |
| Specialized Document Parsing | Requires custom post-processing logic | Built-in parsers for IDs, passports, and invoices |
| Offline Performance | Fully on-device | Fully on-device (usually) |
| Language Support | Broad Latin-based, Chinese, Japanese, etc. | Varies by vendor; often 70+ languages |
| Integration Complexity | Moderate Swift/Objective-C syntax | Varies; often requires custom wrapper setup |
On-Device Versus Cloud Processing
Privacy regulations and latency constraints make on-device processing the preferred architecture for most mobile applications. Running models locally ensures that sensitive user data—such as financial statements, medical records, or personal identification documents—never leaves the device. Cloud-based alternatives offer powerful server-side models but introduce network latency, vulnerability to connection drops, and severe compliance liabilities under privacy frameworks like GDPR and HIPAA.
Multi-Language and Script Support
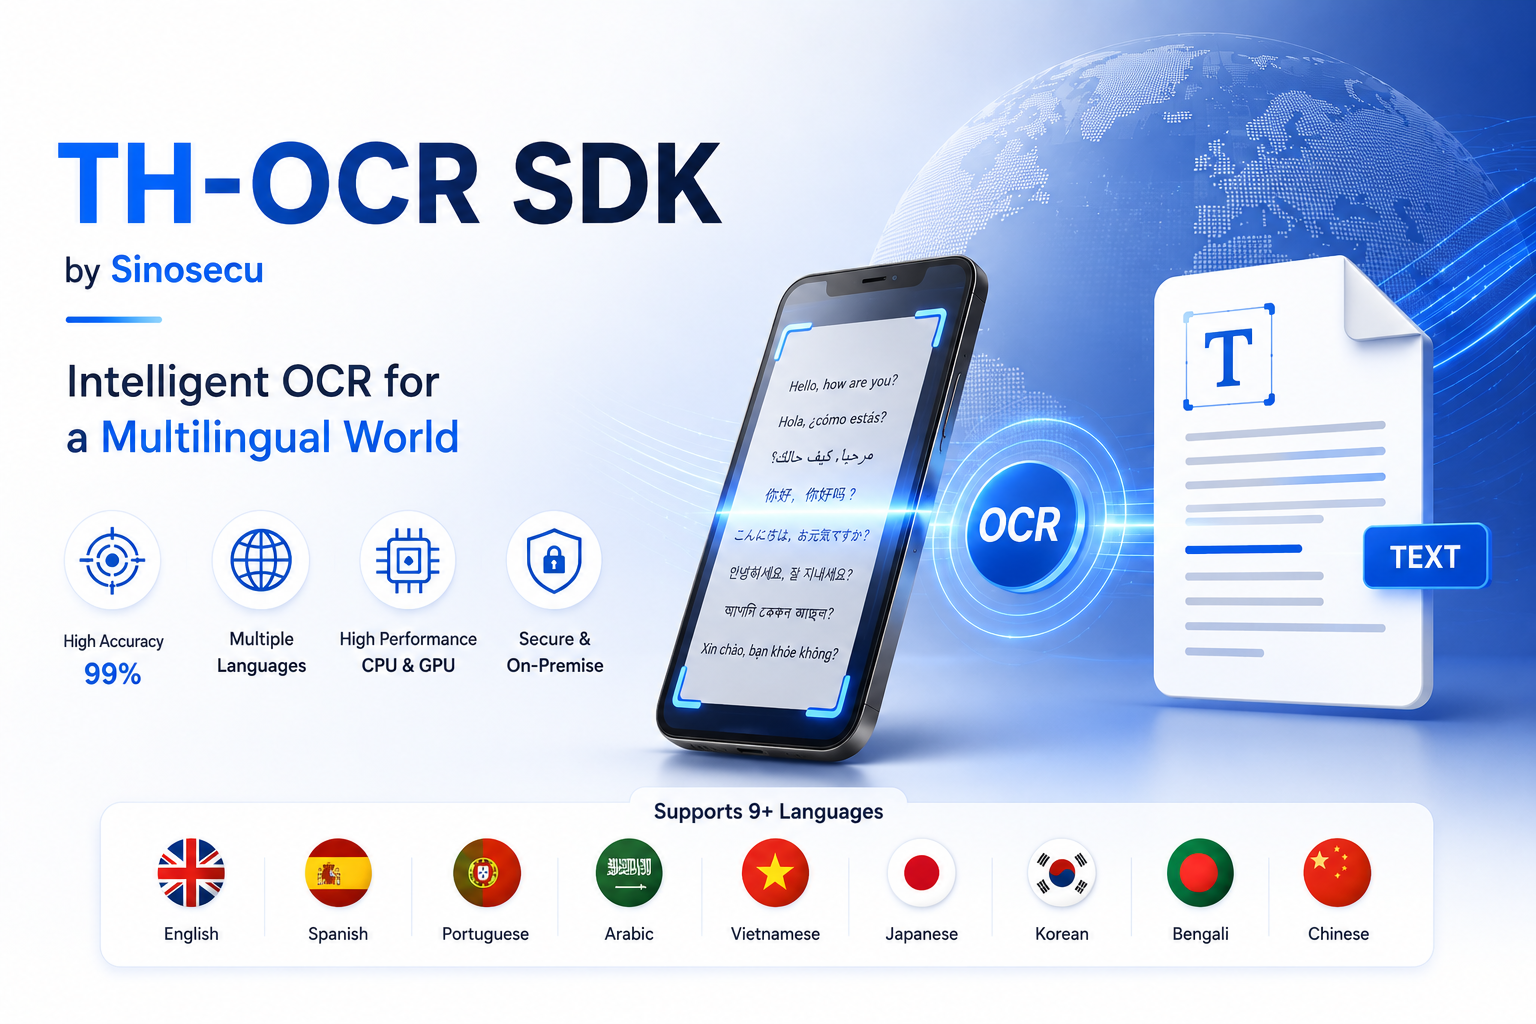
Global applications require robust handling of diverse writing systems. Developers should verify whether the kit supports right-to-left scripts like Arabic and Hebrew, complex non-latin scripts like Devanagari, and character-based systems like Chinese and Japanese. Additionally, mixed-language documents require recognition engines capable of identifying multiple character sets within a single frame simultaneously.
Step-by-Step Implementation Workflow
Implementing a basic live-camera text scanning feature demonstrates the fundamental mechanics of integrating a scanning library into an application architecture.
Configuring Camera Capture Sessions
To extract text in real-time, developers must establish an AVCaptureSession to stream video frames from the device camera.
import AVFoundation import UIKit class CameraCaptureManager: NSObject, AVCaptureVideoDataOutputSampleBufferDelegate { let captureSession = AVCaptureSession() let videoQueue = DispatchQueue(label: "com.example.videoQueue") func setupSession() { captureSession.beginConfiguration() guard let device = AVCaptureDevice.default(.builtInWideAngleCamera, for: .video, position: .back) else { return } guard let input = try? AVCaptureDeviceInput(device: device) else { return } if captureSession.canAddInput(input) { captureSession.addInput(input) } let videoOutput = AVCaptureVideoDataOutput() videoOutput.setSampleBufferDelegate(self, queue: videoQueue) if captureSession.canAddOutput(videoOutput) { captureSession.addOutput(videoOutput) } captureSession.commitConfiguration() } }
Processing Video Sample Buffers
Once the capture session is active, the delegate method receives uncompressed video frames (CMSampleBuffer). These frames are passed directly to the recognition engine without saving them to disk, maximizing performance and maintaining low memory footprints.
func captureOutput(_ output: AVCaptureOutput, didOutput sampleBuffer: CMSampleBuffer, from connection: AVCaptureConnection) { guard let pixelBuffer = CMSampleBufferGetImageBuffer(sampleBuffer) else { return } // Pass pixelBuffer to the text recognition request handler performTextRecognition(on: pixelBuffer) }
Optimizing Performance and User Experience
Achieving a smooth, responsive interface requires careful resource management. Mobile devices have strict thermal limits and battery capacities; intensive machine learning tasks can quickly drain power if left unmanaged.
Frame Throttling and Memory Management
Video streams output roughly 30 frames per second. Running full-image text recognition on every single frame is computationally unnecessary and will cause the application to lag and overheat. Developers should implement frame dropping or throttling logic, processing only every fifth or tenth frame, or triggering intensive recognition only when the user taps a capture button.
Enhancing User Guidance
Real-time scanning relies heavily on proper physical alignment. Providing users with visual overlays, guiding bounding boxes, real-time lighting warnings, and blur detection notifications significantly increases recognition accuracy. Guiding the user to hold the camera steady and parallel to the document eliminates perspective distortion before it reaches the recognition engine.
Common Pitfalls and Troubleshooting
Engineering teams frequently encounter specific hurdles during implementation. Anticipating these challenges prevents costly delays during QA cycles.
- Memory Leaks in Camera Pipelines: Failing to properly invalidate display links, observation tokens, or buffer queues can cause retain cycles. Always tear down capture sessions when navigating away from scanning views.
- Low Contrast and Poor Lighting: Text recognition models fail when shadows obscure text or glare washes out paper surfaces. Implementing programmatic luminance checks helps prompt users to enable the device flashlight.
- Incorrect Orientation Handling: Mobile cameras rotate freely. Failing to pass correct EXIF orientation metadata to the recognition handler results in inverted bounding boxes and failed text extraction.
Frequently Asked Questions
Can text recognition run entirely offline on iOS devices?
Yes. Modern native tools and most enterprise development kits execute fully on-device using the phone's CPU, GPU, or Neural Engine, requiring no active internet connection.
How does Apple's native Vision framework compare to paid commercial SDKs?
Apple's native framework is free, highly optimized, and integrated directly into the operating system. Paid commercial tools often provide specialized templates for structured documents like passports and receipts, saving development time on custom regex parsing.
What is the impact of text recognition on device battery life?
Continuous processing of video streams consumes significant power. Implementing frame throttling, running operations on background dispatch queues, and terminating sessions immediately when scanning concludes helps preserve battery health.
How can developers improve recognition accuracy for handwritten text?
Handwriting recognition requires specialized models trained on varied cursive scripts. Standard printed text models will experience high error rates on handwriting unless the chosen SDK explicitly supports handwriting recognition profiles.
Next Actions for Development Teams
To begin development, audit your application requirements to determine whether native tools suffice or if specialized document parsers justify a commercial license. Build a minimal proof-of-concept focusing on camera capture and frame handling before attempting complex data extraction workflows. Ensure all permission requests and privacy policies clearly communicate how visual data is processed locally on the user's device.