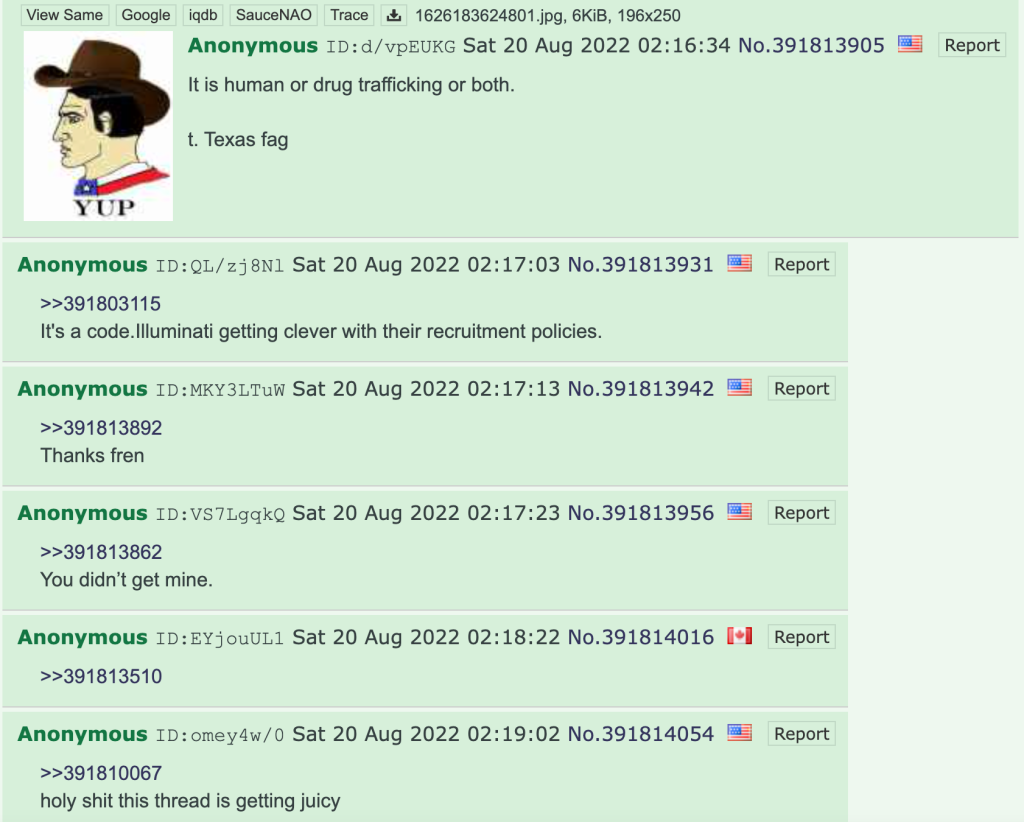
A 4chan archive is a third-party service or software tool designed to capture, store, and display threads from 4chan’s ephemeral imageboards. Because 4chan automatically deletes older content once it is pushed off the final page of a board, these archives serve as vital repositories for researchers and users seeking to retrieve historical discussions and media.
The architecture of 4chan is unique in the modern social media landscape. Unlike platforms such as Reddit or X (formerly Twitter), where content remains accessible indefinitely unless manually deleted, 4chan operates on a "rolling" system. Each board has a fixed number of pages. When a new thread is created, the oldest thread on the last page is permanently "pruned" from 4chan’s servers. 4chan archives bridge this gap by scraping the site’s API in real-time to ensure that cultural milestones, technical discussions, and digital artifacts are preserved before they disappear into the "404 Not Found" void.
The Ephemeral Nature of Imageboards and the Need for Preservation
To understand the necessity of a 4chan archive, one must first understand the lifecycle of a thread. 4chan boards like /v/ (Video Games), /a/ (Anime), or /sci/ (Science & Math) have a "bump limit" and a "page limit." A thread stays active as long as users reply to it, but once it reaches a certain number of replies (usually 300 to 500), it can no longer be "bumped" to the front page. Eventually, as newer threads are created, the old thread slides down the pages until it is deleted.
This ephemerality was a core design choice by the site's founder, but it creates a significant problem for information retention. Valuable technical tutorials, unique digital art, and historical first-hand accounts of global events are lost daily. 4chan archives act as the "library" for this transient data. Without these independent systems, the vast majority of the site’s history since its inception in 2003 would be non-existent to the modern observer.
As of 2026, the ecosystem of archives has become highly specialized. While some archives attempt to index the entire site, most focus on specific boards to manage the massive storage requirements associated with hosting millions of high-resolution images and videos.
How 4chan Archives Function: Technical Mechanics
The process of archiving an imageboard is a complex technical feat involving continuous data ingestion and database management. Most modern archives rely on 4chan’s official JSON API, which provides a structured way to read thread content without the overhead of parsing raw HTML.
Data Ingestion and Scraping
The core of any archive is the "scraper" or "fetcher." Software such as Asagi or the FoolFuuka library is commonly used to monitor 4chan’s API. The scraper checks the "thread list" of a board every few seconds. When it detects a new post or a new image, it downloads the metadata (timestamp, post ID, username/tripcode, and comment text) and the associated media file.
Storage and Hashing
Storage is the most significant challenge for archive operators. 4chan users upload thousands of images every hour. To save space and prevent duplicates, archives use MD5 hashing. When an image is scraped, the system calculates its unique hash. If the archive already contains a file with that exact hash, it simply points the new post to the existing file rather than saving a second copy. This deduplication is essential for maintaining archives that span a decade or more of content.
Database Indexing
For an archive to be useful, it must be searchable. This requires a robust database—often MySQL or PostgreSQL—configured with full-text search capabilities. This allows users to search for specific keywords across billions of posts. In 2026, many archives have integrated advanced filtering, allowing users to sort by "original poster" (OP), date ranges, or even the resolution of the attached images.
Public vs. Private 4chan Archives
There are two primary ways users interact with archived content: through public web-based portals or by running private, localized scraping scripts.
Public Archives
Public archives are websites that provide a searchable frontend for the general public. These sites are often funded by donations or advertisements and are maintained by community volunteers. Examples include legacy names like Warosu, Desustorage, and The Archives. However, the landscape is volatile; these sites frequently go offline due to server costs or legal pressure, leading to "link rot" where old citations no longer function.
Private and Local Archiving
For users who want to ensure a specific thread is never lost, private archiving is the preferred method. In 2026, several open-source tools allow users to "grab" a thread and save it to their local hard drive in a self-contained HTML format. This is common for "hobbyist" archives, where a user might save every thread related to a specific niche interest, such as vintage hardware or obscure linguistics.
| Archive Type | Storage Location | Searchability | Reliability | Technical Difficulty |
|---|---|---|---|---|
| Public Web Archive | Remote Server | High (Global) | Low (Subject to downtime) | Very Low |
| Local Scraper | Personal Drive | Low (Local only) | High (Permanent) | Moderate |
| Wayback Machine | Internet Archive | Very Low | High | Low |
| FoolFuuka Instance | Private Server | High (Custom) | Very High | High |
Advanced Search Techniques for Navigating Archives
Searching a 4chan archive is different from using a standard search engine. Because imageboards are anonymous, you cannot search by "user profile." Instead, you must rely on metadata and content patterns.
- Image MD5 Search: If you have an image and want to find the original thread it came from, many archives allow you to search by the image's hash. This is the most effective way to find the source of a meme or a specific piece of information attached to a graphic.
- Boolean Operators: Most archives support standard Boolean logic. For example, searching
"graphics card" AND "overclock" -RTXwill find threads discussing overclocking graphics cards while excluding those mentioning the "RTX" series. - Thread ID and Post ID: Every post on 4chan has a unique numerical ID. If you have the ID, you can usually jump directly to that post in an archive, even if the thread has been dead for years.
- Date Filtering: Because 4chan's culture shifts rapidly, filtering by year is essential. A search for "crypto" in 2012 yields vastly different results than a search in 2026.
Legal and Ethical Considerations of Archiving
The practice of archiving 4chan is fraught with legal and ethical complexities. Because the site is unmoderated in many respects, archives often inadvertently host content that violates copyright or local laws.
DMCA and Content Takedowns
Public archives are generally subject to the Digital Millennium Copyright Act (DMCA). If a copyright holder finds their material on an archive, they can issue a takedown notice. Reliable archives usually comply with these requests to avoid being de-indexed by search engines or shut down by their hosting providers.
Privacy and Anonymity
While 4chan is anonymous, users sometimes post "dox" (personally identifiable information) or private photos. While the original thread on 4chan may disappear in an hour, an archive makes that information permanent. This "right to be forgotten" is a major point of contention. Most archive administrators provide a contact method for removing sensitive personal information, though the speed of response varies wildly.
Malware and Safety
Archived threads can contain links to malicious websites or files. Furthermore, because archives store images exactly as they were posted, they may contain graphic or disturbing content. Users should approach 4chan archives with the same caution they would use on the live site, utilizing script-blockers and updated antivirus software.
The Role of Archives in Academic Research
In 2026, 4chan archives have become primary sources for sociologists, linguists, and political scientists. The site is often viewed as a "laboratory" for internet culture, where language evolves at an accelerated rate.
- Linguistic Analysis: Researchers use archives to track the origin and spread of slang terms and neologisms.
- Political Science: Archives provide a chronological record of political movements and the spread of "counter-culture" ideologies.
- Memeology: By looking at the first appearance of an image hash across various archives, historians can pinpoint exactly when and where a global meme was born.
The data provided by these archives is often raw and unfiltered, offering a look at human behavior that is not sanitized by the corporate algorithms found on Facebook or LinkedIn. This makes the 4chan archive an uncomfortable but necessary tool for understanding the modern internet.
Common Mistakes When Using 4chan Archives
Navigating these systems requires a specific mindset. New users often encounter frustrations due to the way data is indexed.
- Expecting Total Coverage: No archive captures 100% of 4chan. High-traffic boards like /b/ (Random) are so fast that scrapers often miss posts during server lag. If you cannot find a thread, it may simply have been missed during the ingestion process.
- Ignoring "Ghost" Images: Sometimes an archive will save the text of a post but fail to download the image before the original was deleted. In these cases, you will see a placeholder. There is generally no way to recover these "ghost" images once they are gone from the live site.
- Misinterpreting "Tripcodes": Archives display tripcodes (a way for anonymous users to verify their identity). It is important to remember that tripcodes can be "cracked" or shared. Just because a post in 2015 and a post in 2026 use the same tripcode does not strictly guarantee they are the same person.
Setting Up a Personal Archive Instance
For those interested in data science or extreme digital preservation, setting up a personal instance of an archive is the only way to ensure data sovereignty.
Prerequisites
To run a full-scale archive like FoolFuuka, you will need a Linux-based server (Ubuntu or Debian are standard), a significant amount of NVMe or SSD storage for the database, and massive HDD arrays for image storage. As of 2026, archiving a single high-traffic board for one year can easily consume several terabytes of space.
Installation Steps
- Environment Setup: Install Nginx, PHP-FPM, and MariaDB/MySQL.
- Fetcher Configuration: Set up a scraper like Asagi. This tool runs in the background and "calls" the 4chan API at set intervals.
- Database Optimization: Because 4chan archives grow to millions of rows quickly, proper indexing on the
post_idandtimestampcolumns is mandatory to prevent the search function from crashing. - Media Storage: Configure a storage path, ideally on a separate volume, to handle the influx of image files.
Frequently Asked Questions
Are 4chan archives legal to use?
Accessing and searching a 4chan archive is generally legal in most jurisdictions, as you are simply viewing cached web content. However, hosting an archive can be legally complex due to copyright (DMCA) and regional laws regarding prohibited content. Users should always follow local regulations regarding the viewing of sensitive or restricted material.
Can I delete a post I made from a 4chan archive?
Most public archives are not affiliated with 4chan. Deleting a post on the live 4chan site will not remove it from an archive. To have a post removed, you must contact the administrator of the specific archive site. Some archives have "report" buttons for this purpose, while others require a formal email. Success rates vary depending on whether the content violates the archive's own terms of service.
Why do some images show up as "File Not Found" on archives?
This usually occurs due to "scraping lag." If 4chan's servers are under heavy load, the API might report the text of a post before the image is fully distributed across their Content Delivery Network (CDN). If the thread is deleted very quickly (common in "fast" boards), the archive's scraper might never get the chance to download the media file, leaving only the text and metadata.
Is there a "master" archive that has everything?
No. Due to the sheer volume of data—estimated in the petabytes over the site's 20-plus year history—no single entity hosts every post and image from every board. The archival effort is decentralized. Some sites specialize in "Blue Boards" (work-safe), while others focus on "Red Boards" (not-work-safe).
How do I find a thread from 10 years ago?
The best approach is to use a dedicated board archive (like Warosu for /ck/ or /tg/) and search by specific, unique keywords that would have appeared in the original post (OP). If the board-specific archive doesn't have it, the Wayback Machine is a secondary option, though it rarely captures full threads or all images.
Practical Recommendations for Users
If you are looking for a specific piece of information from 4chan's past, start by identifying which board the discussion likely occurred on. Navigate to a reputable public archive dedicated to that board and use the MD5 search if you have a related image. For those who find a currently active thread that they consider "essential," do not rely on public archives to catch it. Use a browser extension or a local script to save a "Full Web Page" copy of the thread immediately. This ensures that even if the public archives face a DMCA takedown or technical failure, your personal copy remains intact.